Introduction
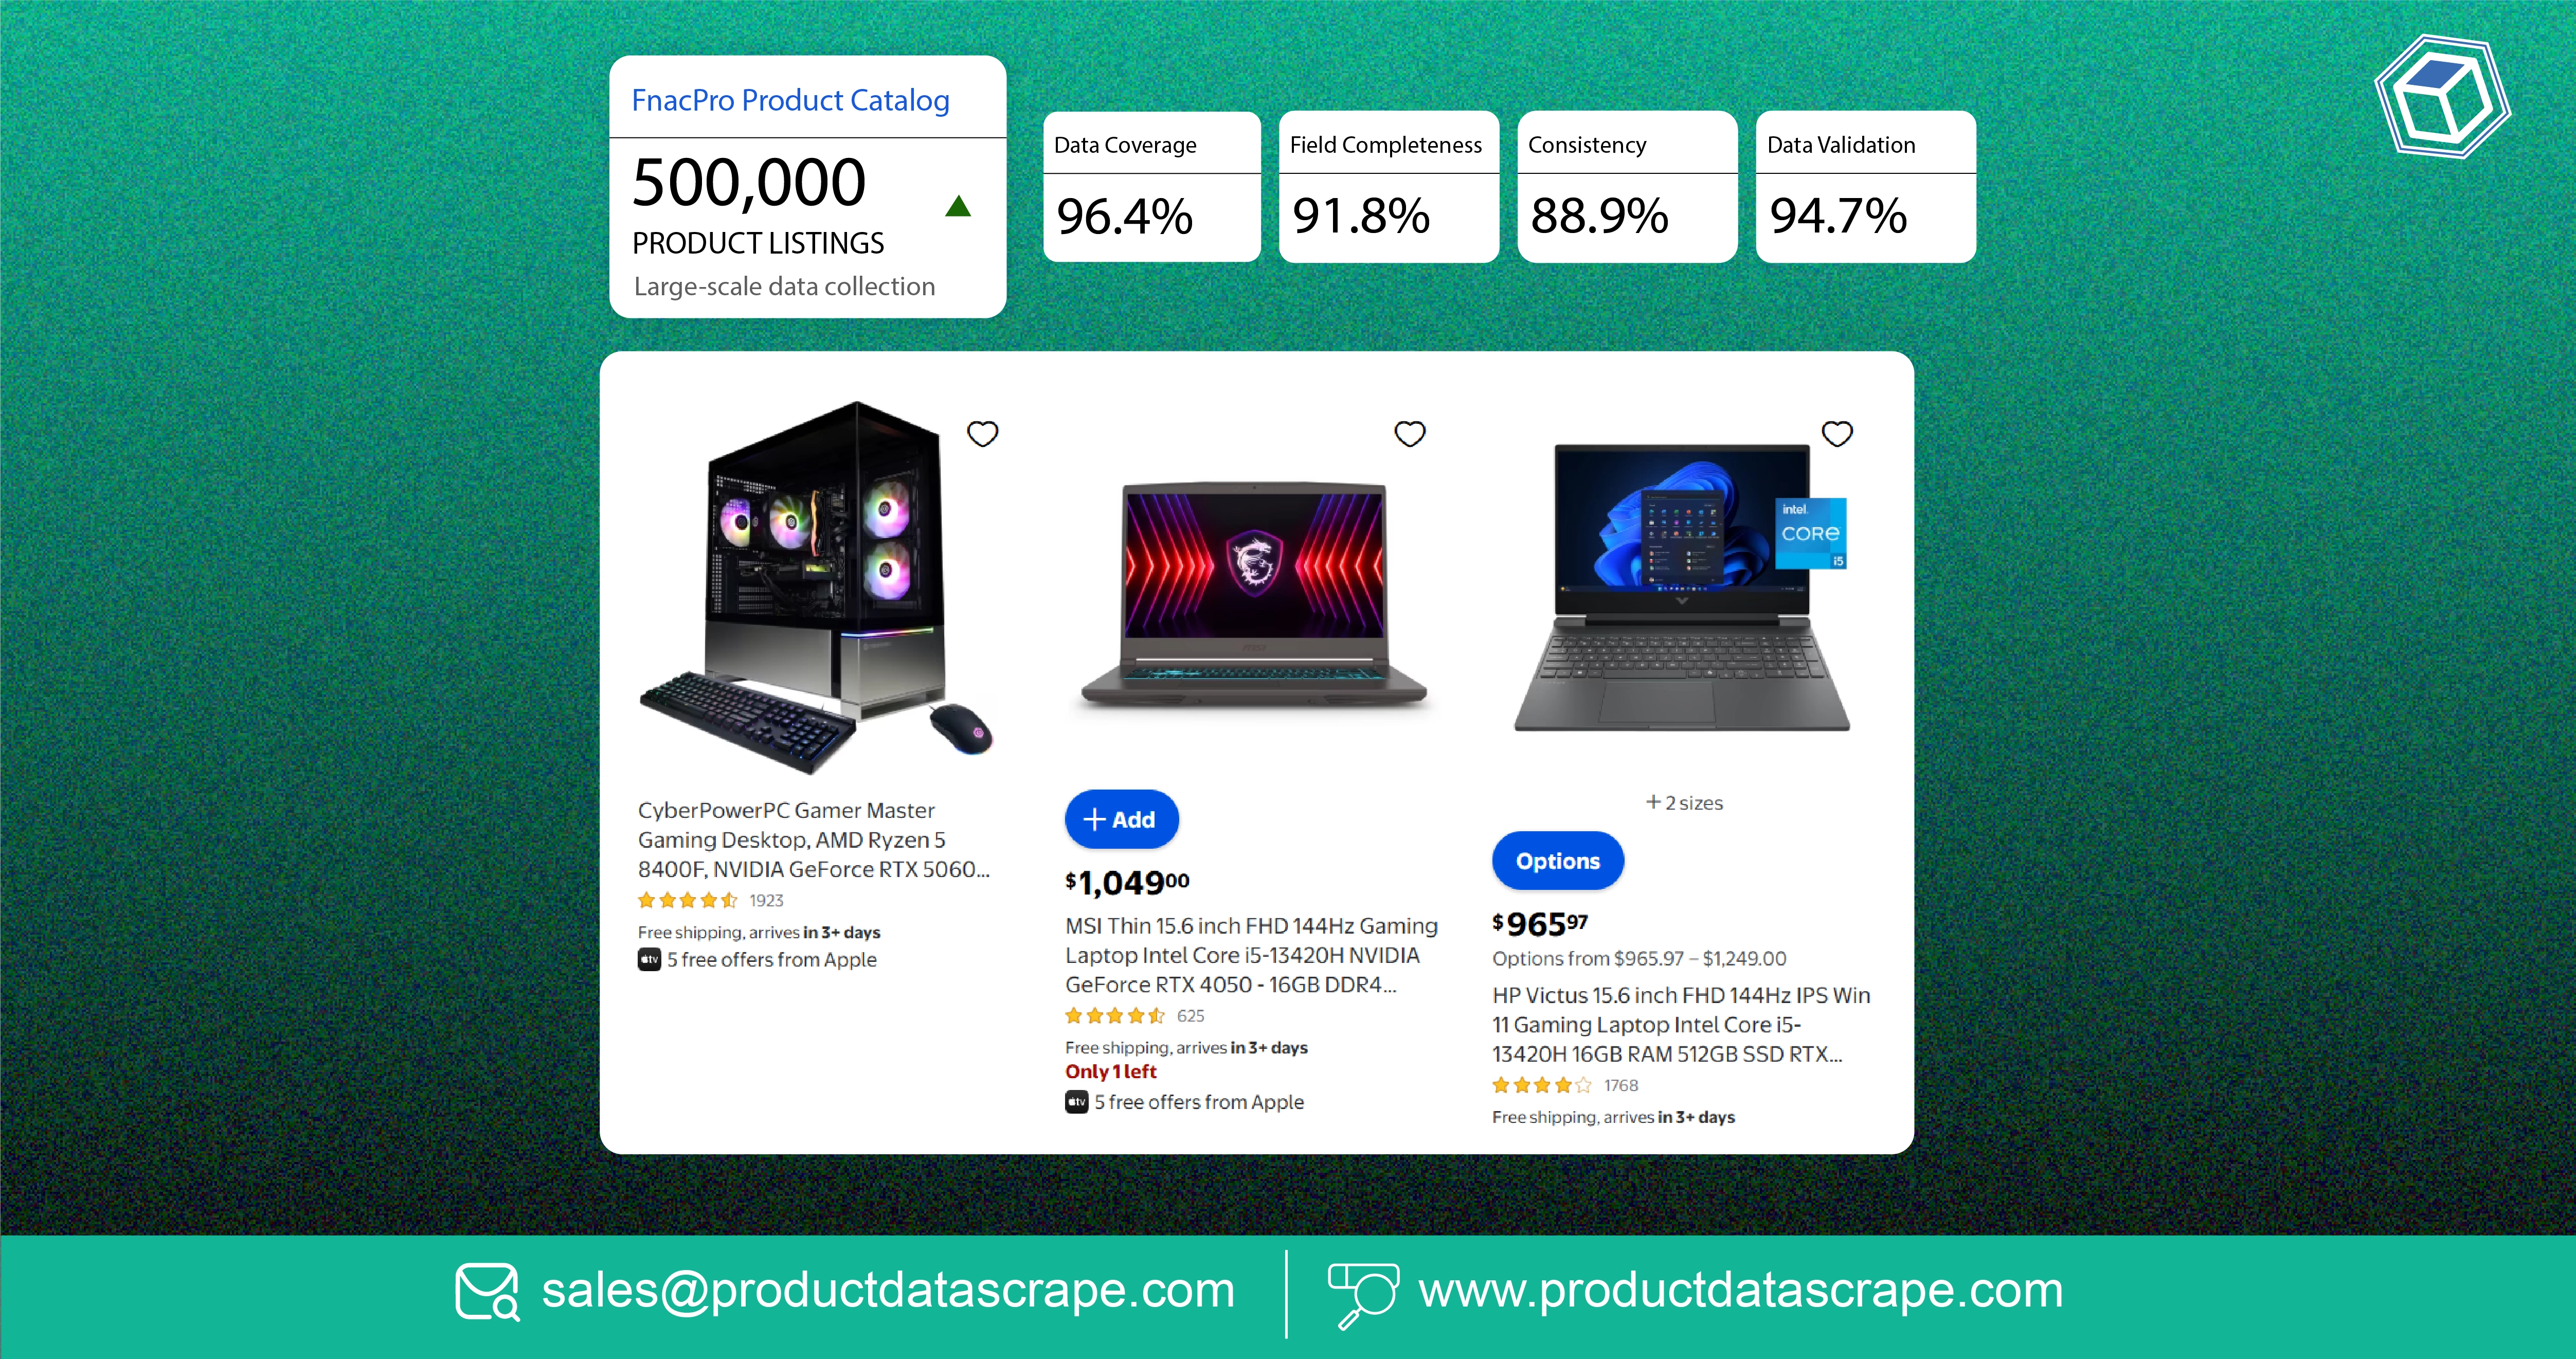
Scrape 500,000 FnacPro Product Listings to build a structured view of products, prices, categories, SKUs, specifications, and availability. Large-scale extraction helps e-commerce teams replace fragmented product information with a consistent dataset for market research, catalog management, pricing analysis, and competitive intelligence.
Industry data point: Global e-commerce sales are projected to continue growing through 2026, increasing the need for accurate product information and faster competitive monitoring. Large catalogs can contain hundreds of thousands of changing records, making manual collection impractical.
For retailers, distributors, marketplace sellers, and market research teams, product data gaps create direct business problems. Missing SKUs can distort assortment analysis. Outdated availability data can affect purchasing decisions. Inconsistent prices can weaken competitive research.
A scalable collection strategy addresses these challenges by organizing product information into usable datasets. Teams can monitor product changes, compare prices, identify assortment gaps, and evaluate market positioning.
The goal is not simply to collect a large volume of records. The goal is to create reliable, structured, and reusable product intelligence.
What Does Assortment and Availability Monitoring Solve?
Assortment and availability monitoring helps businesses understand which products are listed, which products are unavailable, and how catalog depth changes over time. This information supports procurement, sales planning, competitor research, and marketplace strategy.
How Can Businesses Track Product Availability More Accurately?
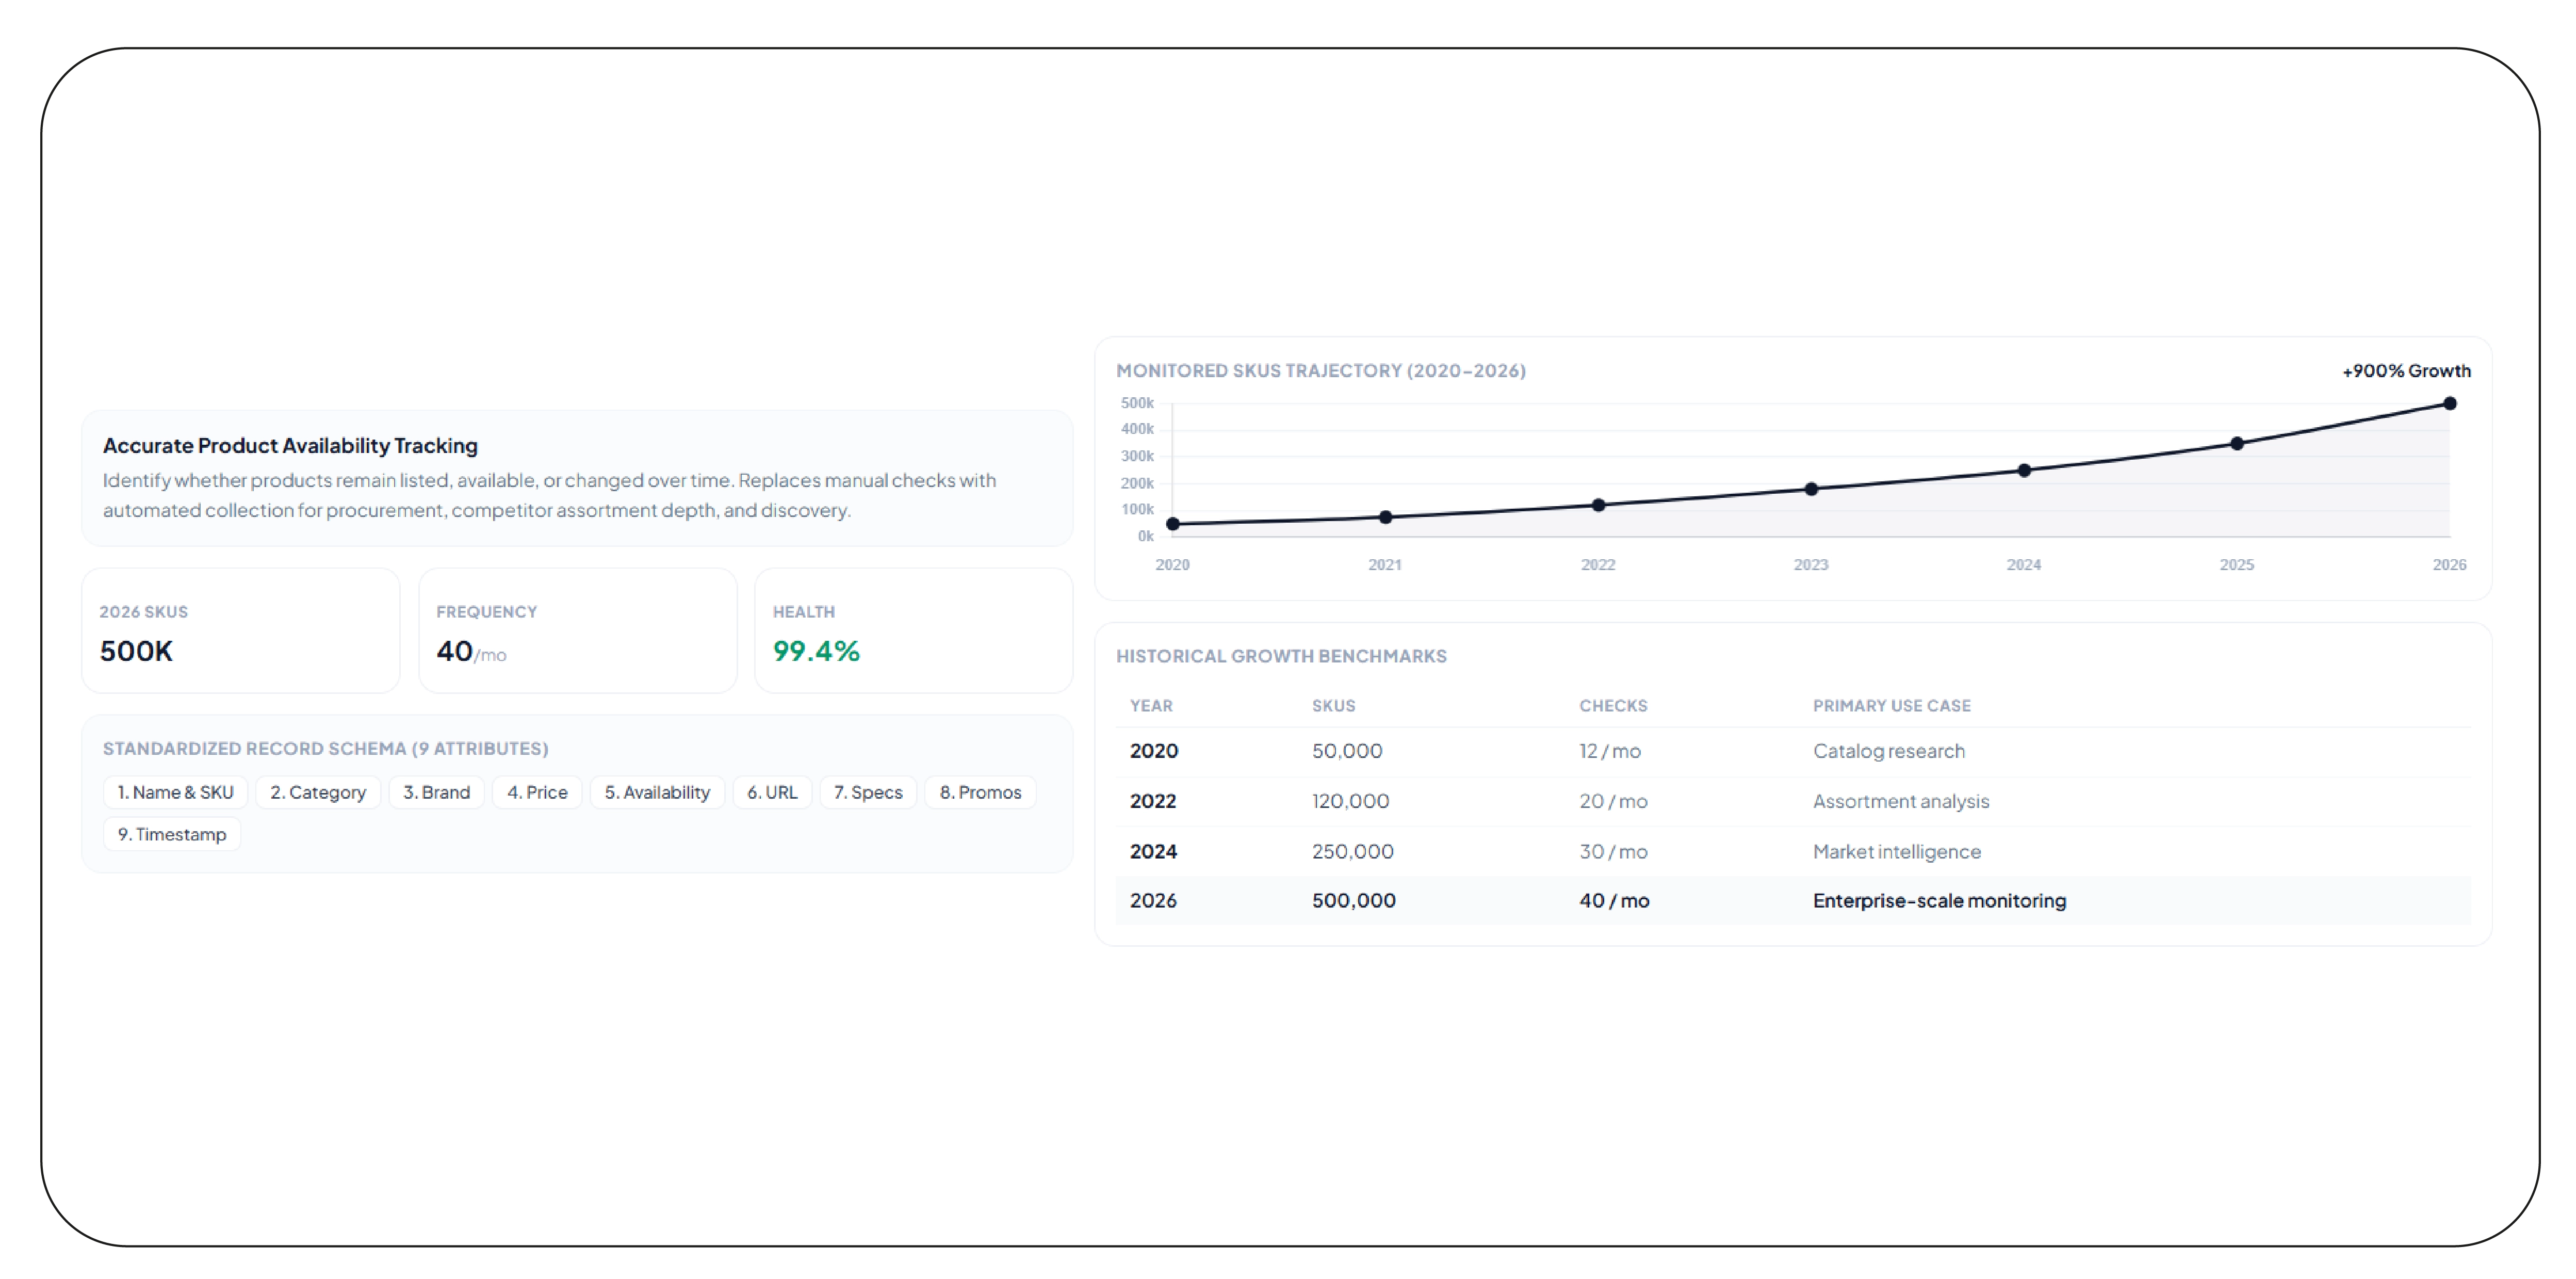
Product availability tracking FnacPro helps businesses identify whether individual products remain listed, available, unavailable, or changed over time. This creates a practical foundation for monitoring large catalogs without relying on manual checks.
A large product catalog can change frequently. Products may disappear, return to stock, change categories, or receive updated specifications. Automated collection allows teams to capture these changes at regular intervals and compare new records with historical datasets.
For procurement teams, availability information can reveal supply gaps. For retailers, it can show competitor assortment depth. For distributors, it can support product discovery and sales planning.
A structured monitoring process should capture:
- Product name and SKU
- Product category
- Brand
- Current price
- Availability status
- Product URL
- Specifications
- Promotional information
- Collection timestamp
Historical records make the dataset more useful. Teams can compare availability across months and identify recurring patterns.
| Year |
Hypothetical monitored SKUs |
Availability checks |
Primary use |
| 2020 |
50,000 |
12/month |
Catalog research |
| 2021 |
75,000 |
15/month |
Supply monitoring |
| 2022 |
120,000 |
20/month |
Assortment analysis |
| 2023 |
180,000 |
25/month |
Competitive research |
| 2024 |
250,000 |
30/month |
Market intelligence |
| 2025 |
350,000 |
35/month |
Pricing and supply analysis |
| 2026 |
500,000 |
40/month |
Enterprise-scale monitoring |
These figures are illustrative rather than reported FnacPro measurements. They show how monitoring requirements can grow as catalog coverage expands.
The key benefit is consistency. Instead of checking thousands of pages manually, businesses can work from standardized product records and historical snapshots.
How Does SKU-Level Extraction Improve Product Intelligence?
SKU-level product data extraction gives businesses a detailed view of individual products instead of relying on broad category information. Each SKU can become a separate record with its own price, specifications, availability, brand, and category attributes.
This level of detail matters because two products in the same category may have different configurations, prices, stock conditions, and commercial value. SKU-level records allow teams to compare products precisely.
For example, a technology distributor may need to distinguish between different storage capacities or configurations. A business supplies retailer may need to compare pack sizes or product variants. Without SKU-level information, these differences can disappear inside aggregated datasets.
A strong extraction workflow can capture:
- SKU or product identifier.
- Product title.
- Brand and manufacturer.
- Category and subcategory.
- Product specifications.
- Current price.
- Availability.
- Product rating where available.
- Product URL.
- Extraction date.
| Year |
Hypothetical SKU records |
Data attributes per SKU |
Business focus |
| 2020 |
40,000 |
8 |
Basic catalog research |
| 2021 |
65,000 |
10 |
Product comparison |
| 2022 |
100,000 |
12 |
Retail intelligence |
| 2023 |
160,000 |
14 |
Assortment analysis |
| 2024 |
240,000 |
16 |
Competitive intelligence |
| 2025 |
350,000 |
18 |
Pricing analysis |
| 2026 |
500,000 |
20 |
Enterprise product intelligence |
These are hypothetical planning figures. They illustrate how data depth can increase alongside catalog scale.
SKU-level extraction also improves data quality. Teams can detect duplicate products, missing attributes, inconsistent naming, and unexpected price changes.
When product information follows a consistent schema, analysts can easily filter, compare, aggregate, and visualize the data. This turns raw catalog pages into a practical dataset for decision-making.
What Makes Large Catalog Extraction Useful for Market Research?
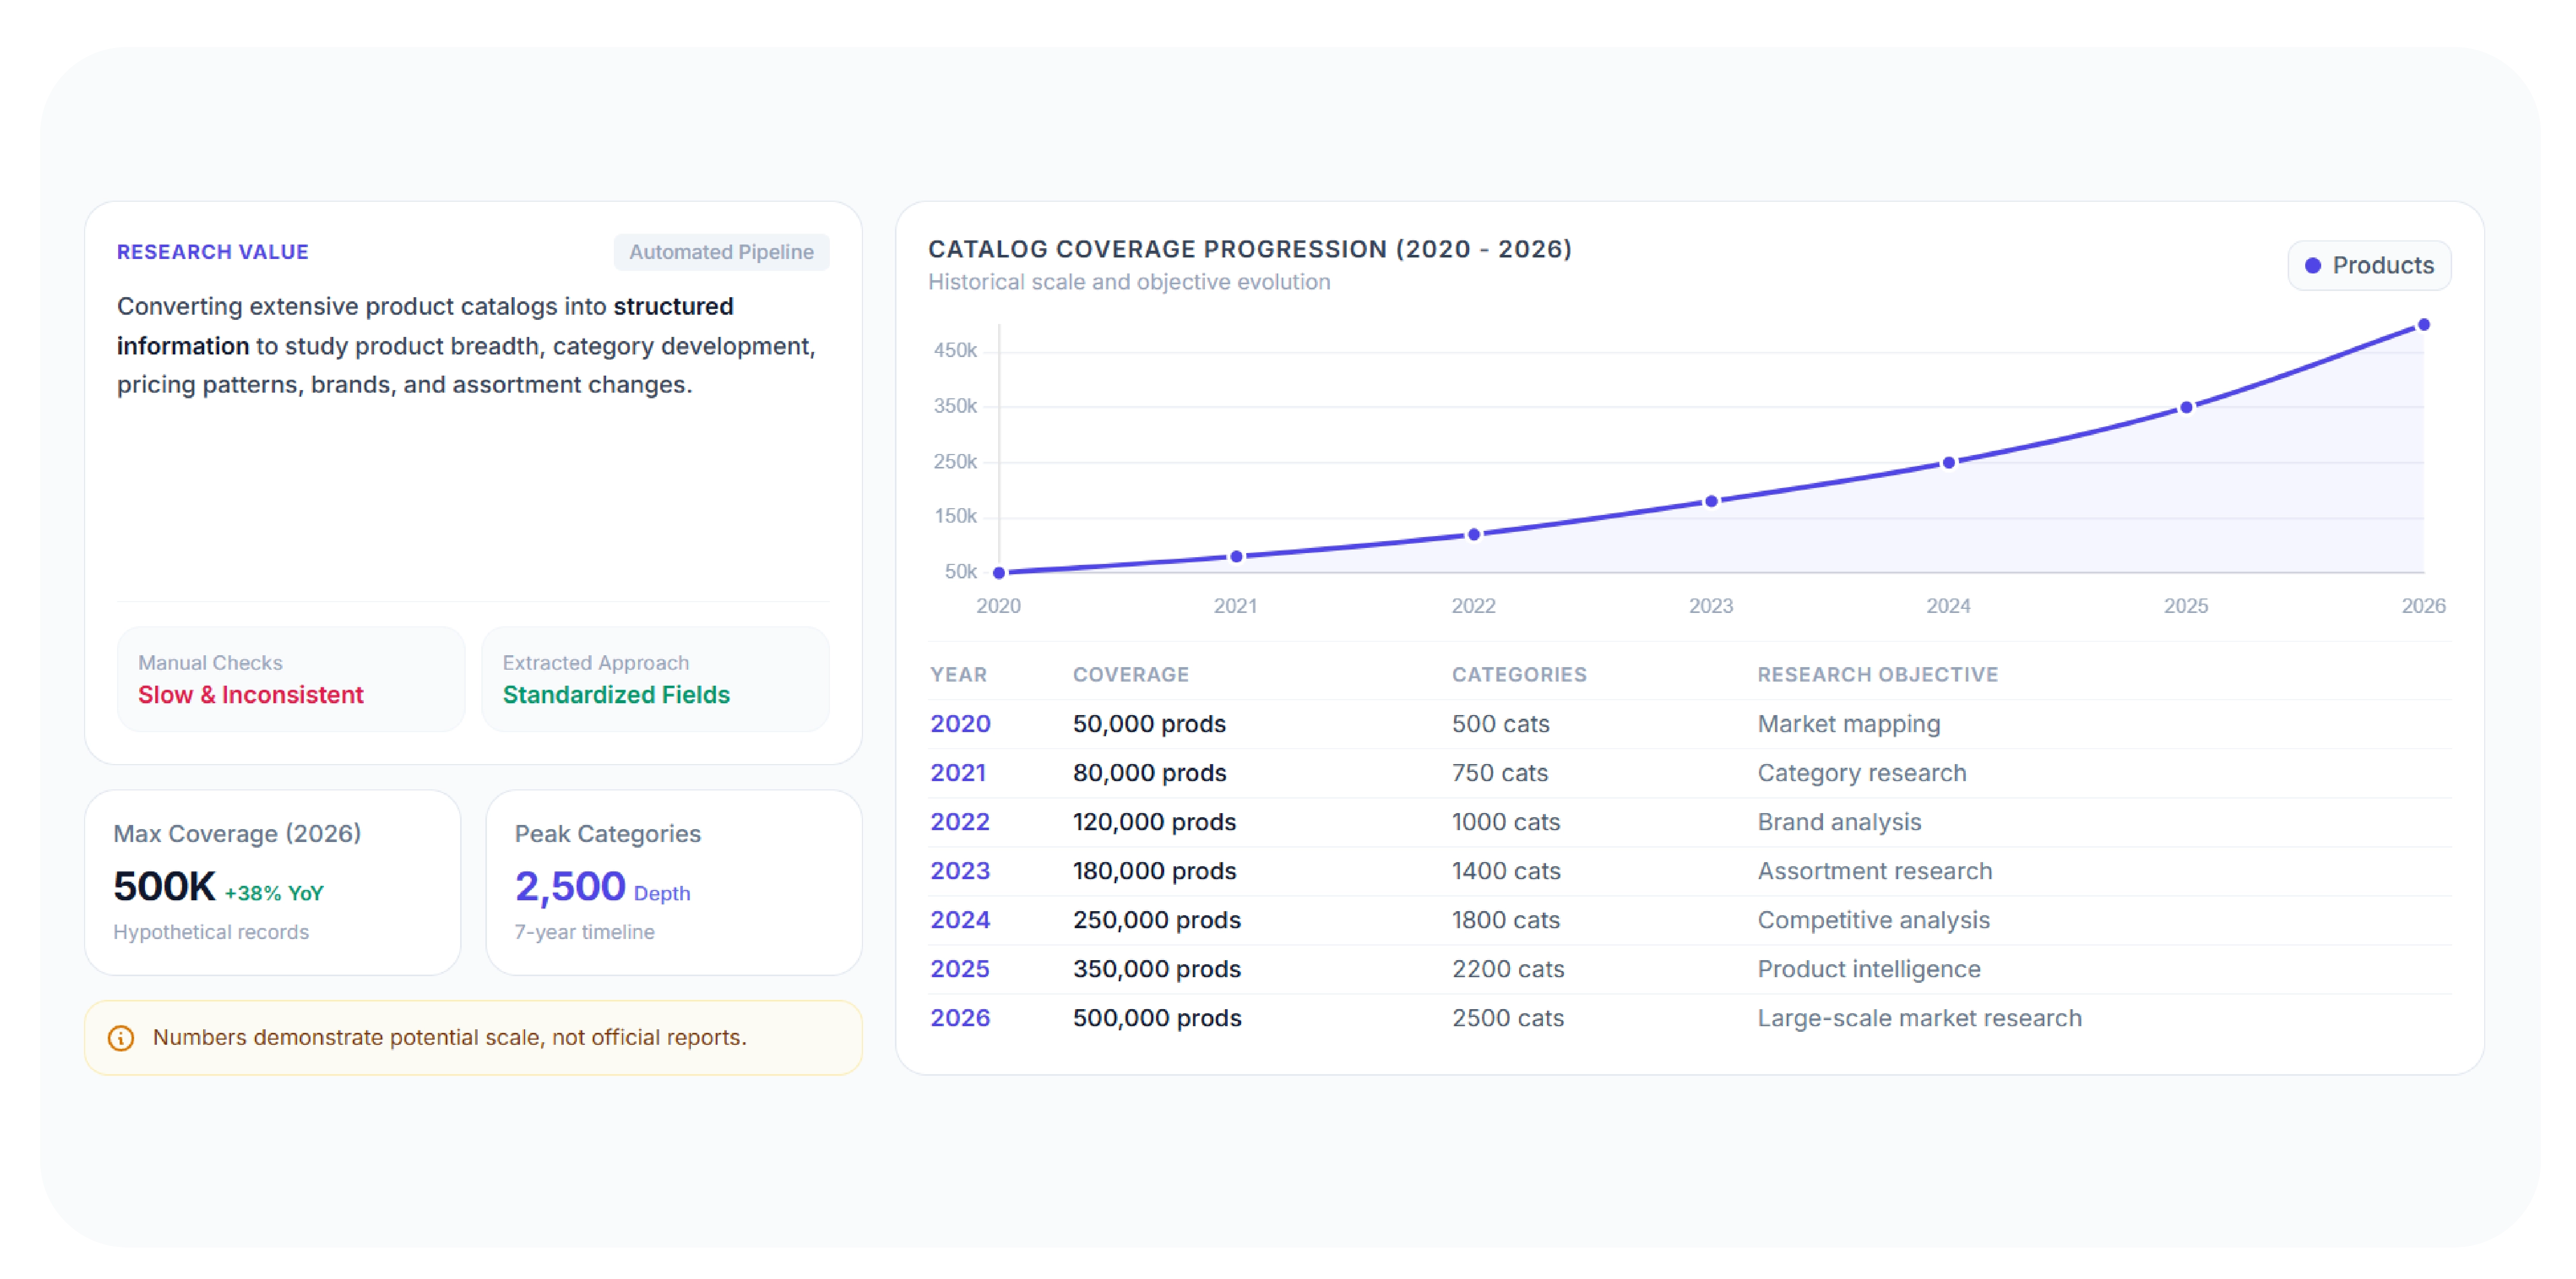
FnacPro catalog data extraction can support market research by converting extensive product catalogs into structured information. Researchers can use this information to study product breadth, category development, pricing patterns, brands, and assortment changes.
Catalog research becomes difficult when businesses depend on occasional manual checks. A product catalog may contain thousands of categories and hundreds of thousands of individual records. Manual collection takes time and can introduce inconsistencies.
A scalable approach creates standardized fields across the catalog. Researchers can then compare product groups using the same criteria.
Useful fields include:
- Category
- Subcategory
- Product title
- Brand
- Manufacturer
- SKU
- Price
- Availability
- Specifications
- Product attributes
- Collection date
| Year |
Hypothetical catalog coverage |
Categories analyzed |
Research objective |
| 2020 |
50,000 products |
500 |
Market mapping |
| 2021 |
80,000 products |
750 |
Category research |
| 2022 |
120,000 products |
1,000 |
Brand analysis |
| 2023 |
180,000 products |
1,400 |
Assortment research |
| 2024 |
250,000 products |
1,800 |
Competitive analysis |
| 2025 |
350,000 products |
2,200 |
Product intelligence |
| 2026 |
500,000 products |
2,500 |
Large-scale market research |
The numbers above are hypothetical and demonstrate potential scale rather than FnacPro-reported catalog statistics.
Historical datasets provide another advantage. Businesses can compare catalogs across periods and identify products that were added, removed, renamed, or repositioned.
This supports several research questions. Which categories are expanding? Which brands have greater assortment depth? Which products remain consistently available? Where are catalog gaps appearing?
For buyers and analysts, these answers can support better sourcing and market decisions.
How Can Availability Data Reveal Changes in Product Assortment?
Product availability tracking FnacPro can help businesses understand how product assortments change over time. Availability is not simply a stock indicator. It can also provide a signal about catalog movement and potential market opportunities.
When a product repeatedly becomes unavailable, businesses may investigate whether the issue reflects demand, supply constraints, seasonal changes, or catalog restructuring. When new products appear frequently, teams can identify emerging categories and product trends.
Availability monitoring becomes especially valuable when combined with historical product records. A single snapshot shows the current state. Multiple snapshots reveal movement.
Businesses can analyze:
- New product additions.
- Removed products.
- Reappearing products.
- Persistent unavailable items.
- Category-level availability.
- Brand-level assortment changes.
- Seasonal availability patterns.
| Year |
Hypothetical product records |
Change events tracked |
Potential insight |
| 2020 |
50,000 |
100,000 |
Basic assortment movement |
| 2021 |
75,000 |
150,000 |
Product expansion |
| 2022 |
120,000 |
240,000 |
Category growth |
| 2023 |
180,000 |
360,000 |
Brand movement |
| 2024 |
250,000 |
500,000 |
Assortment optimization |
| 2025 |
350,000 |
700,000 |
Supply monitoring |
| 2026 |
500,000 |
1,000,000 |
Enterprise intelligence |
These are illustrative figures designed to demonstrate how monitoring volume can increase as catalog size grows.
Availability data can also improve internal reporting. Procurement teams can prioritize products with recurring supply issues. Sales teams can identify products with stable availability. Analysts can study category-level movements.
The result is a more complete understanding of the marketplace. Instead of viewing products as static records, businesses can evaluate them as changing commercial assets.
How Can Competitive Pricing Data Support Better Decisions?
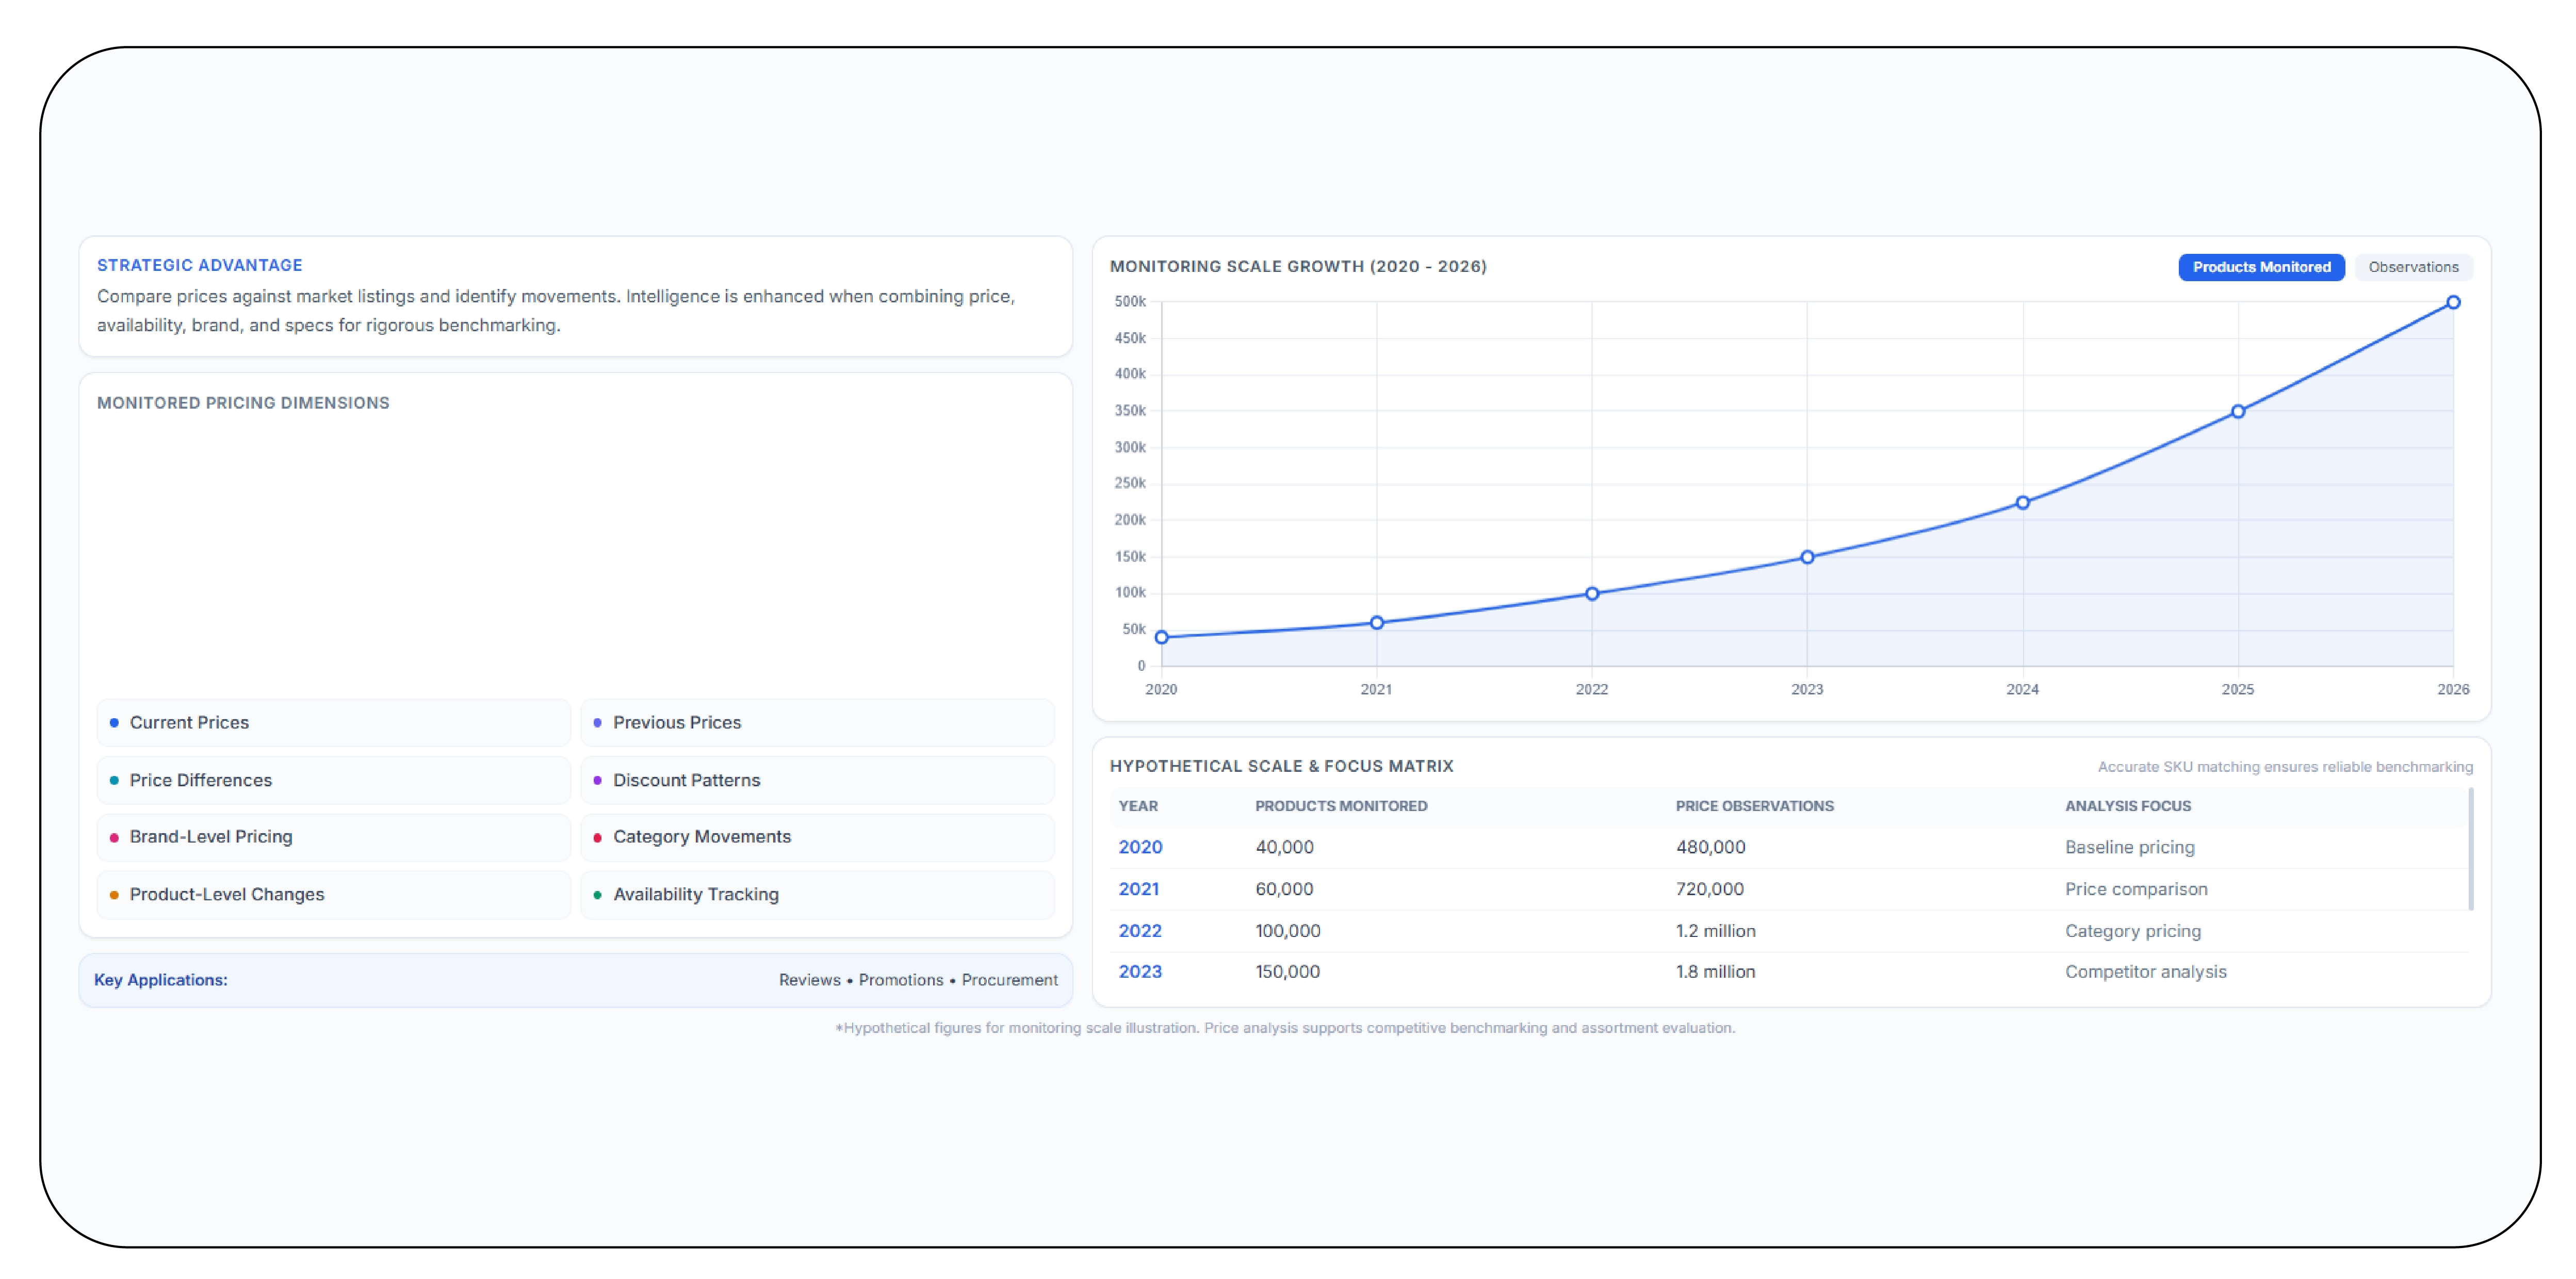
Competitive pricing data helps businesses compare their own prices against market listings and identify meaningful pricing movements. Price intelligence becomes more effective when businesses collect comparable product information at scale.
A simple price snapshot can answer what a product costs today. Historical price data can answer a more valuable question: how has that price changed?
Businesses can monitor:
- Current product prices.
- Previous prices.
- Price differences.
- Discount patterns.
- Brand-level pricing.
- Category-level price movements.
- Product-level price changes.
- Availability alongside pricing.
| Year |
Hypothetical products monitored |
Price observations |
Analysis focus |
| 2020 |
40,000 |
480,000 |
Baseline pricing |
| 2021 |
60,000 |
720,000 |
Price comparison |
| 2022 |
100,000 |
1.2 million |
Category pricing |
| 2023 |
150,000 |
1.8 million |
Competitor analysis |
| 2024 |
225,000 |
2.7 million |
Dynamic monitoring |
| 2025 |
350,000 |
4.2 million |
Pricing intelligence |
| 2026 |
500,000 |
6 million |
Large-scale analysis |
These figures are hypothetical examples for illustrating monitoring scale.
Price analysis becomes stronger when SKU matching is accurate. Businesses should compare equivalent products rather than products that merely share similar names.
Combining price, availability, brand, and specifications creates a richer competitive picture. Analysts can identify products with unusual price movements, categories with aggressive pricing, and areas where their own assortment may be uncompetitive.
This information can support pricing reviews, promotional planning, procurement decisions, and competitive benchmarking.
What Can Pricing Services Do With Historical Product Data?
Pricing strategy services can turn historical product records into actionable pricing insights. Instead of reviewing individual prices manually, businesses can analyze patterns across categories, brands, SKUs, and time periods.
Historical data provides context. A price change may appear significant in isolation, but it may be normal for a particular category. Comparing multiple observations helps analysts understand the difference between routine movement and meaningful competitive shifts.
A pricing workflow can include:
- Collect product and price records.
- Standardize product identifiers.
- Match comparable SKUs.
- Store historical observations.
- Detect price changes.
- Segment products by category.
- Compare competitive positions.
- Generate pricing reports.
| Year |
Hypothetical pricing records |
Main analytical capability |
| 2020 |
500,000 |
Historical baselines |
| 2021 |
750,000 |
Price comparisons |
| 2022 |
1.2 million |
Category benchmarking |
| 2023 |
1.8 million |
Competitive monitoring |
| 2024 |
2.7 million |
Trend identification |
| 2025 |
4.2 million |
Pricing optimization |
| 2026 |
6 million |
Automated intelligence |
Again, these are illustrative figures rather than reported FnacPro statistics.
Pricing intelligence can support different buyer personas. E-commerce managers can evaluate competitive positioning. Procurement teams can negotiate with better market knowledge. Marketplace sellers can identify pricing opportunities. Analysts can study category-level movements.
The strongest strategy combines pricing with availability and product attributes. A low price means something different when the product is unavailable. A price premium may be justified by specifications, brand, or configuration.
Large-scale historical data makes these relationships easier to identify and measure.
Why Choose Product Data Scrape?
Product Data Scrape provides a structured approach to large-scale product intelligence. It helps businesses organize product records into useful datasets for research, competitive analysis, catalog management, and pricing decisions.
A scalable workflow can reduce manual collection work while improving consistency across large product catalogs. Teams can focus on analysis instead of repeatedly checking individual pages.
The approach supports structured fields, historical comparisons, SKU-level analysis, and large-volume datasets. This makes it suitable for retailers, distributors, marketplace sellers, procurement teams, and market researchers.
For businesses managing extensive catalogs, reliable data collection can improve visibility across products, prices, specifications, and availability. Better visibility supports faster decisions and stronger market intelligence.
How Does Catalog Enrichment Improve Product Intelligence?
Catalog Enrichment adds useful attributes to raw product records and makes them easier to analyze. Enriched datasets can include standardized titles, brands, categories, specifications, SKUs, prices, availability, and timestamps.
Scrape 500,000 FnacPro Product Listings can provide the volume needed to build broad product datasets for large-scale analysis. Businesses can then organize these records according to their internal schemas and reporting requirements.
Enrichment also helps reduce inconsistent product information. Standardized fields make it easier to compare products across categories and identify missing attributes.
For e-commerce teams, better catalog quality can improve product discovery and competitive research. For analysts, structured attributes make segmentation and benchmarking easier.
What Should Businesses Consider Before Starting Large-Scale Extraction?
Large-scale product data projects require more than volume. Businesses should define their data fields, refresh frequency, storage structure, quality rules, and intended use before beginning.
A practical project should consider:
- Scope: Define the categories and product fields required.
- Scale: Estimate the number of products and records.
- Frequency: Decide how often data needs refreshing.
- Quality: Validate missing, duplicate, and inconsistent records.
- History: Store timestamps for trend analysis.
- Normalization: Use consistent product and category structures.
- Monitoring: Track changes between collection cycles.
- Output: Choose formats that fit analytics and business systems.
A 500,000-product dataset can generate substantial value, but only when the information remains structured and usable.
Businesses should also distinguish between raw extraction and actionable intelligence. Raw data provides records. Clean, normalized, historical data provides insight.
What Business Problems Can a Large Product Dataset Solve?
Large product datasets can address several common e-commerce and market intelligence problems. They can help businesses understand assortment gaps, monitor availability, benchmark prices, enrich catalogs, and identify competitive movements.
For retailers, product intelligence can support assortment planning. For distributors, it can support sourcing and market analysis. For marketplace sellers, it can help evaluate competitive positioning.
For research teams, historical datasets can reveal changes that are difficult to see from individual product pages.
The most important benefit is visibility. Businesses gain a structured way to evaluate thousands or hundreds of thousands of product records without depending entirely on manual research.
When product information becomes standardized, teams can ask better questions and make decisions with greater confidence.
Why Is Historical Data Important for Product Research?
Historical data provides context that current listings cannot provide alone. A current product price does not reveal whether it recently increased, decreased, or remained stable. A current availability status does not explain whether the product has repeatedly gone unavailable.
Historical datasets allow businesses to compare records across dates and identify patterns.
This supports:
- Product lifecycle analysis.
- Price trend analysis.
- Assortment change tracking.
- Availability monitoring.
- Category growth research.
- Brand movement analysis.
- Competitive benchmarking.
The 2020–2026 period also illustrates how businesses can build increasingly detailed datasets over time. The hypothetical tables in this article show how monitoring volume can scale from tens of thousands of products to hundreds of thousands.
The objective should remain consistent: collect relevant information, maintain historical context, and turn structured records into useful business intelligence.
Conclusion
Large product catalogs contain valuable information, but businesses need structured and timely data to use it effectively. Large-scale extraction can reveal product availability, SKU details, catalog changes, pricing movements, and competitive opportunities.
For retailers, distributors, marketplace sellers, and research teams, this information can strengthen assortment planning and market analysis. Historical records also make it easier to identify changes instead of relying on isolated snapshots.
Marketplace selling intelligence becomes more useful when product, price, availability, and catalog information work together. A scalable dataset can turn fragmented product pages into a practical source of business insight.
Start building scalable product intelligence today with Product Data Scrape and discover how to Scrape 500,000 FnacPro Product Listings for better competitive, catalog, and pricing analysis!
FAQs
1. What is the benefit of collecting 500,000 product listings?
Collecting 500,000 listings can provide broad visibility into products, prices, categories, availability, brands, and specifications for competitive research, assortment analysis, and market intelligence.
2. Which product fields should businesses collect?
Important fields include SKU, product name, brand, category, price, availability, specifications, product URL, and collection timestamp for reliable historical product analysis.
3. Can large product datasets support pricing analysis?
Yes. Historical product prices can help businesses compare competitors, identify price movements, benchmark categories, and evaluate pricing opportunities using structured product records.
4. How can Product Data Scrape support large catalogs?
Product Data Scrape can support structured product-data workflows designed around large catalogs, helping teams organize product information for analysis, monitoring, and competitive intelligence.
5. How often should product information be refreshed?
Refresh frequency depends on business needs. High-change categories may require frequent monitoring, while stable catalogs may need weekly or monthly collection cycles.


 Singapore
 EMAIL
 PHONE






.webp)