Quick Overview
Client name: Not provided · Industry: Book retail and distribution · Service: Seller price intelligence · Duration: To be confirmed
The project focuses on organizing seller-level pricing observations for a large book catalog. The scope supplied is 150,000 ISBNs, with the top five seller prices targeted for comparison. An ISBN uniquely identifies a particular book title and edition or format, making it a useful identifier for catalog matching.
The proposed Amazon India seller data scraping workflow organizes observable product and offer information into structured records, while Scrape Amazon Review & Rating Data can be a separate data stream where publicly displayed review information is within the agreed scope. The final case study should report verified coverage, data completeness, refresh frequency, and processing performance only after project records confirm them.
The Client
Book retailers, distributors, and publishers operate in a market where a single title may have multiple editions, formats, and competing offers. Accurate product identification is important because different editions or formats can have different ISBNs. The International ISBN Agency explains that each distinct title format or edition requires its own ISBN.
For a brand managing a large online book assortment, comparing seller prices across 150,000 ISBNs can help organize competitive research around individual book editions instead of relying on broad category averages. Amazon India ISBN Price Data Scraping describes the intended collection of observable pricing information associated with matching book identifiers. The broader practice of Price scraping can help create time-stamped records for examining changes between collection periods.
Before implementation, the client's exact starting conditions must be documented. These may include whether product identifiers and seller offers were already stored in spreadsheets, how frequently prices were checked, which attributes were missing, and whether the existing process could preserve historical observations. These are assessment questions, not confirmed facts about the client.
The project brief establishes the intended scale and comparison objective but does not identify the brand, its previous workflow, or any measured operational problems. Those details should be added from approved client interviews, project documentation, or implementation records before publication.
Amazon provides a Selling Partner API for authorized seller and vendor workflows, including access to relevant selling data. Its product-pricing documentation describes pricing and offer information, although the availability of particular data depends on the API, permissions, and marketplace context.
Goals and Objectives
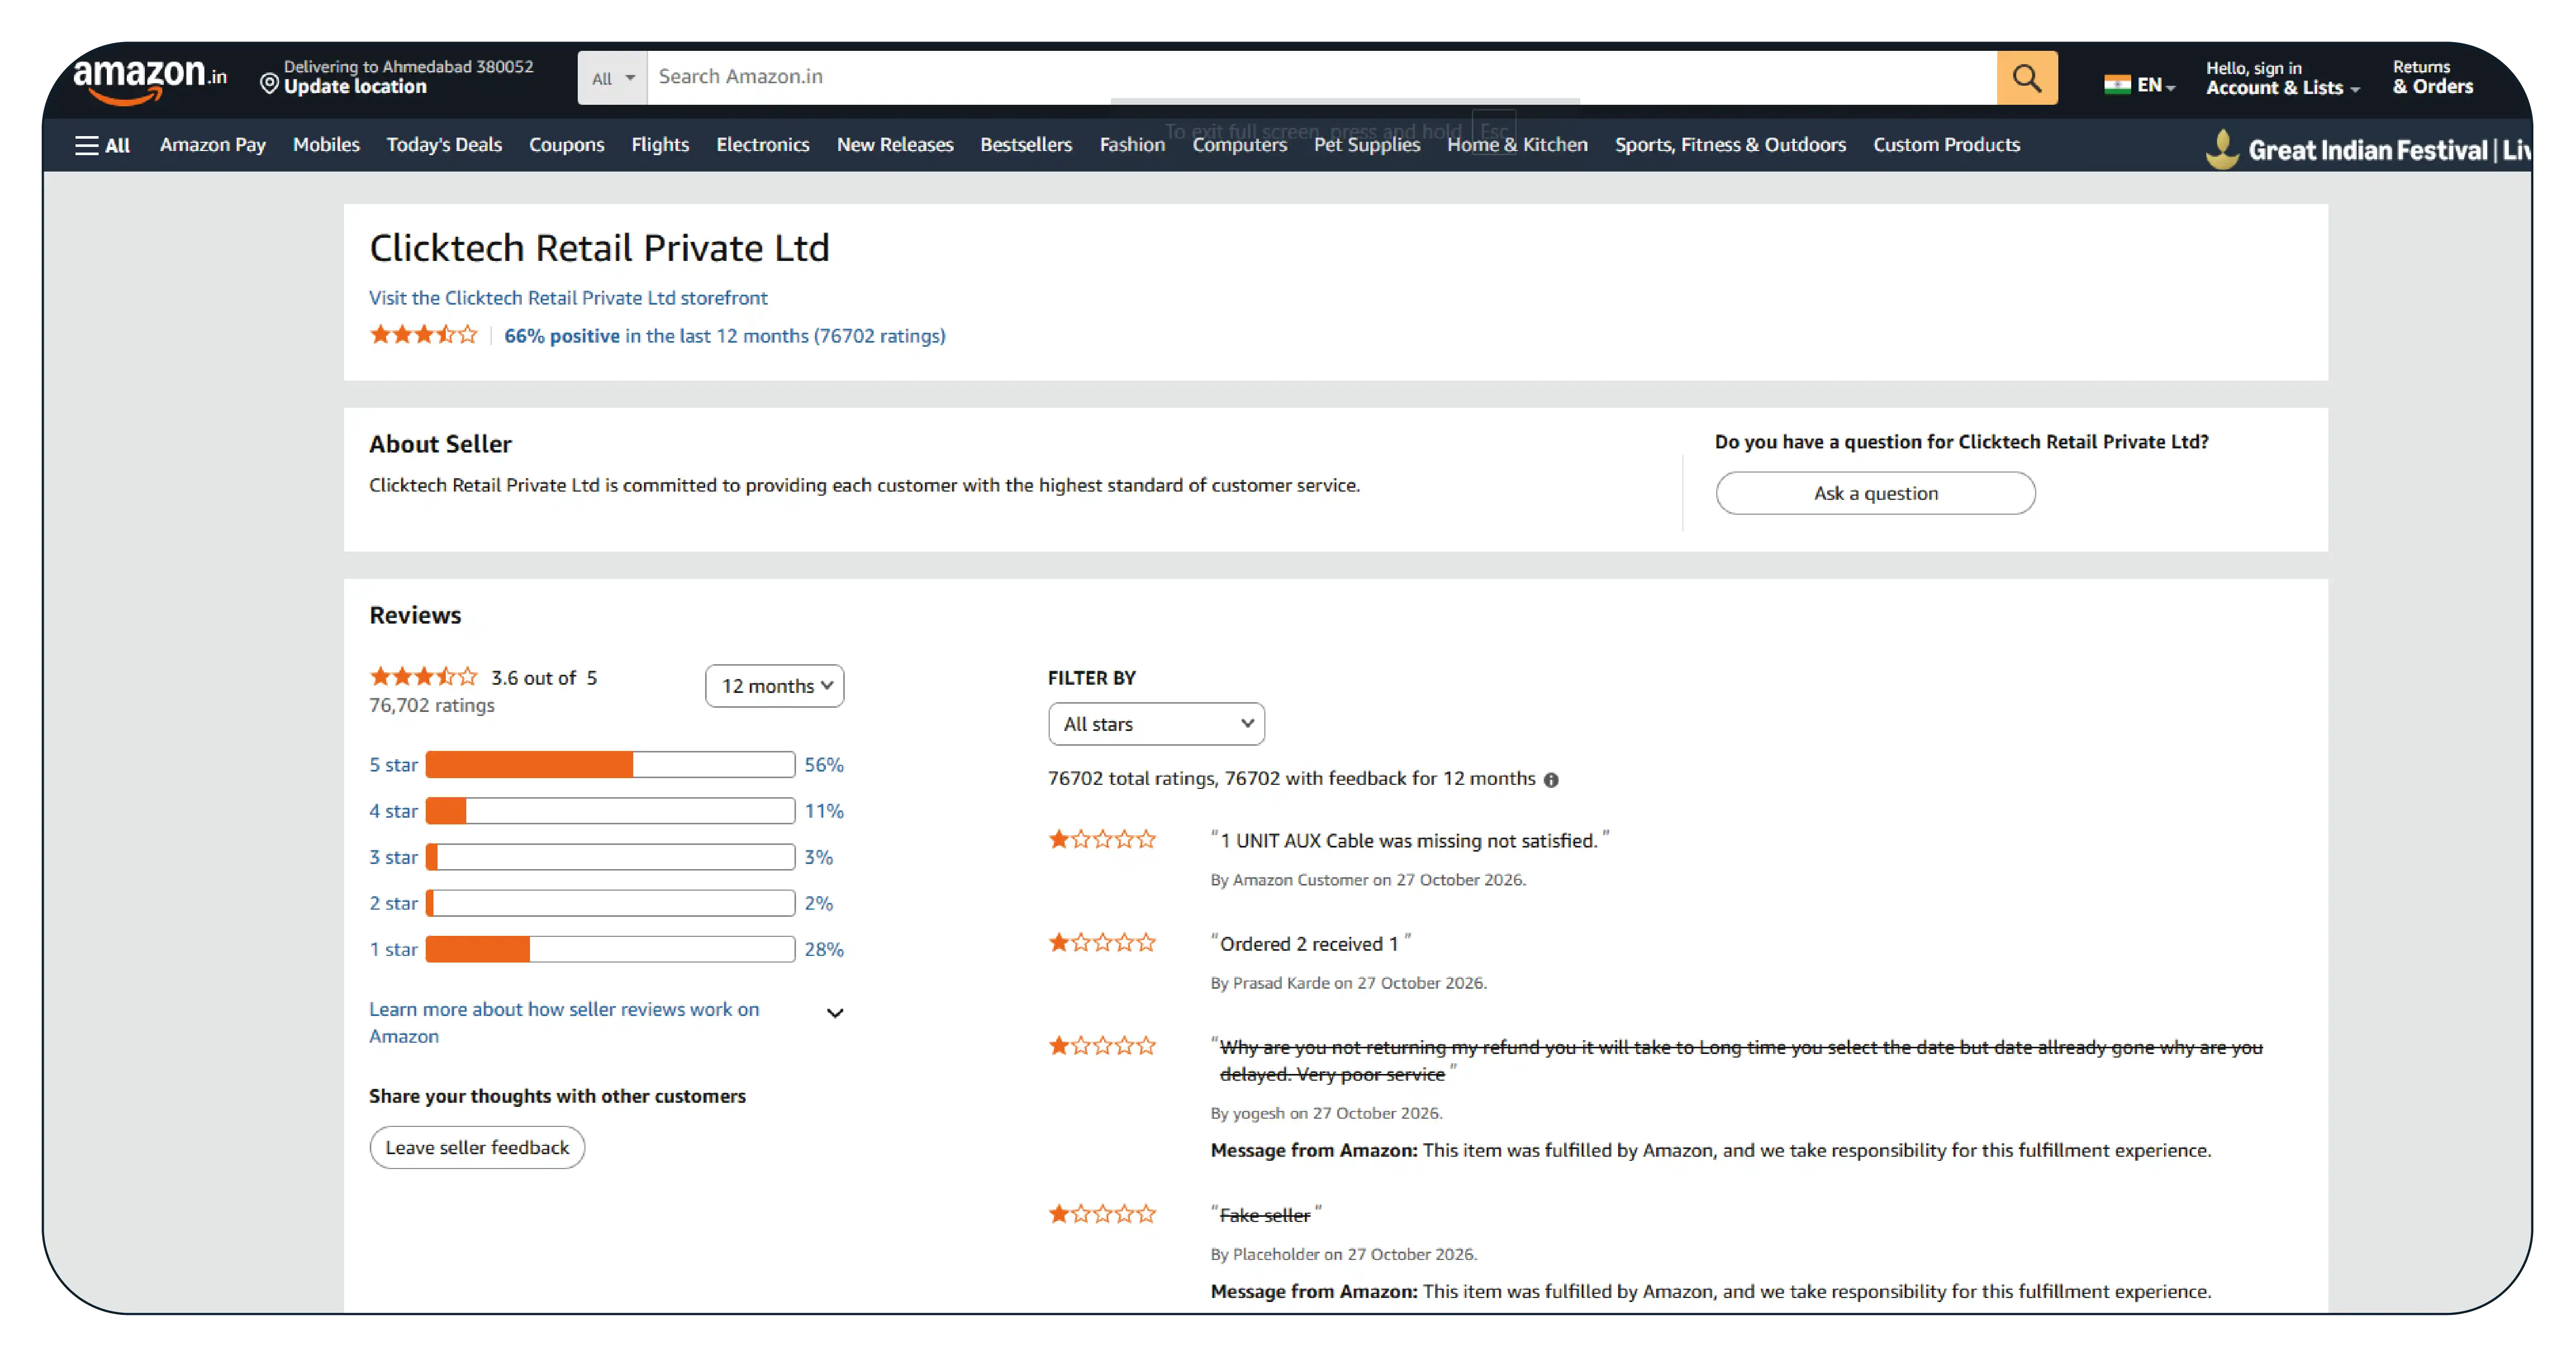
The primary business goal was to establish a consistent approach for comparing the top five seller prices across a target catalog of 150,000 ISBNs. ISBN Based Book Data Extraction provides the identifier-led foundation for connecting product records with their corresponding offers.
The intended outcomes include better visibility into observed price differences, easier identification of missing records, and a repeatable framework for competitive research. The workflow should also distinguish listed prices from discounts, shipping charges, and other offer components whenever the source provides enough information.
The technical objective for E-commerce data scraping for the India was to define a structured collection process that could support catalog matching, seller comparison, data validation, and scheduled refreshes.
The proposed implementation includes:
Normalize ISBNs and validate identifier formats.
Match product records to the correct title and edition.
Capture available seller names, observed prices, product URLs, and collection timestamps.
Preserve separate fields for list prices, sale prices, and shipping where available.
Detect duplicates and flag missing or conflicting records.
Store historical snapshots to support price comparisons over time.
Export structured data into the client's approved reporting environment.
These are proposed technical objectives; the completed implementation should be confirmed against project documentation.
The following indicators can be measured without assuming unverified improvements:
Catalog coverage: Number of the 150,000 target ISBNs successfully matched.
Seller coverage: Number of matched ISBNs with five identifiable seller offers.
Field completeness: Percentage of records containing required pricing and product fields.
Match accuracy: Percentage of audited records correctly matched to the intended edition.
Refresh timeliness: Time required to complete an agreed collection cycle.
Duplicate rate: Percentage of redundant records detected during validation.
Baseline and post-implementation values should be reported only after the project data has been audited.
The Core Challenge
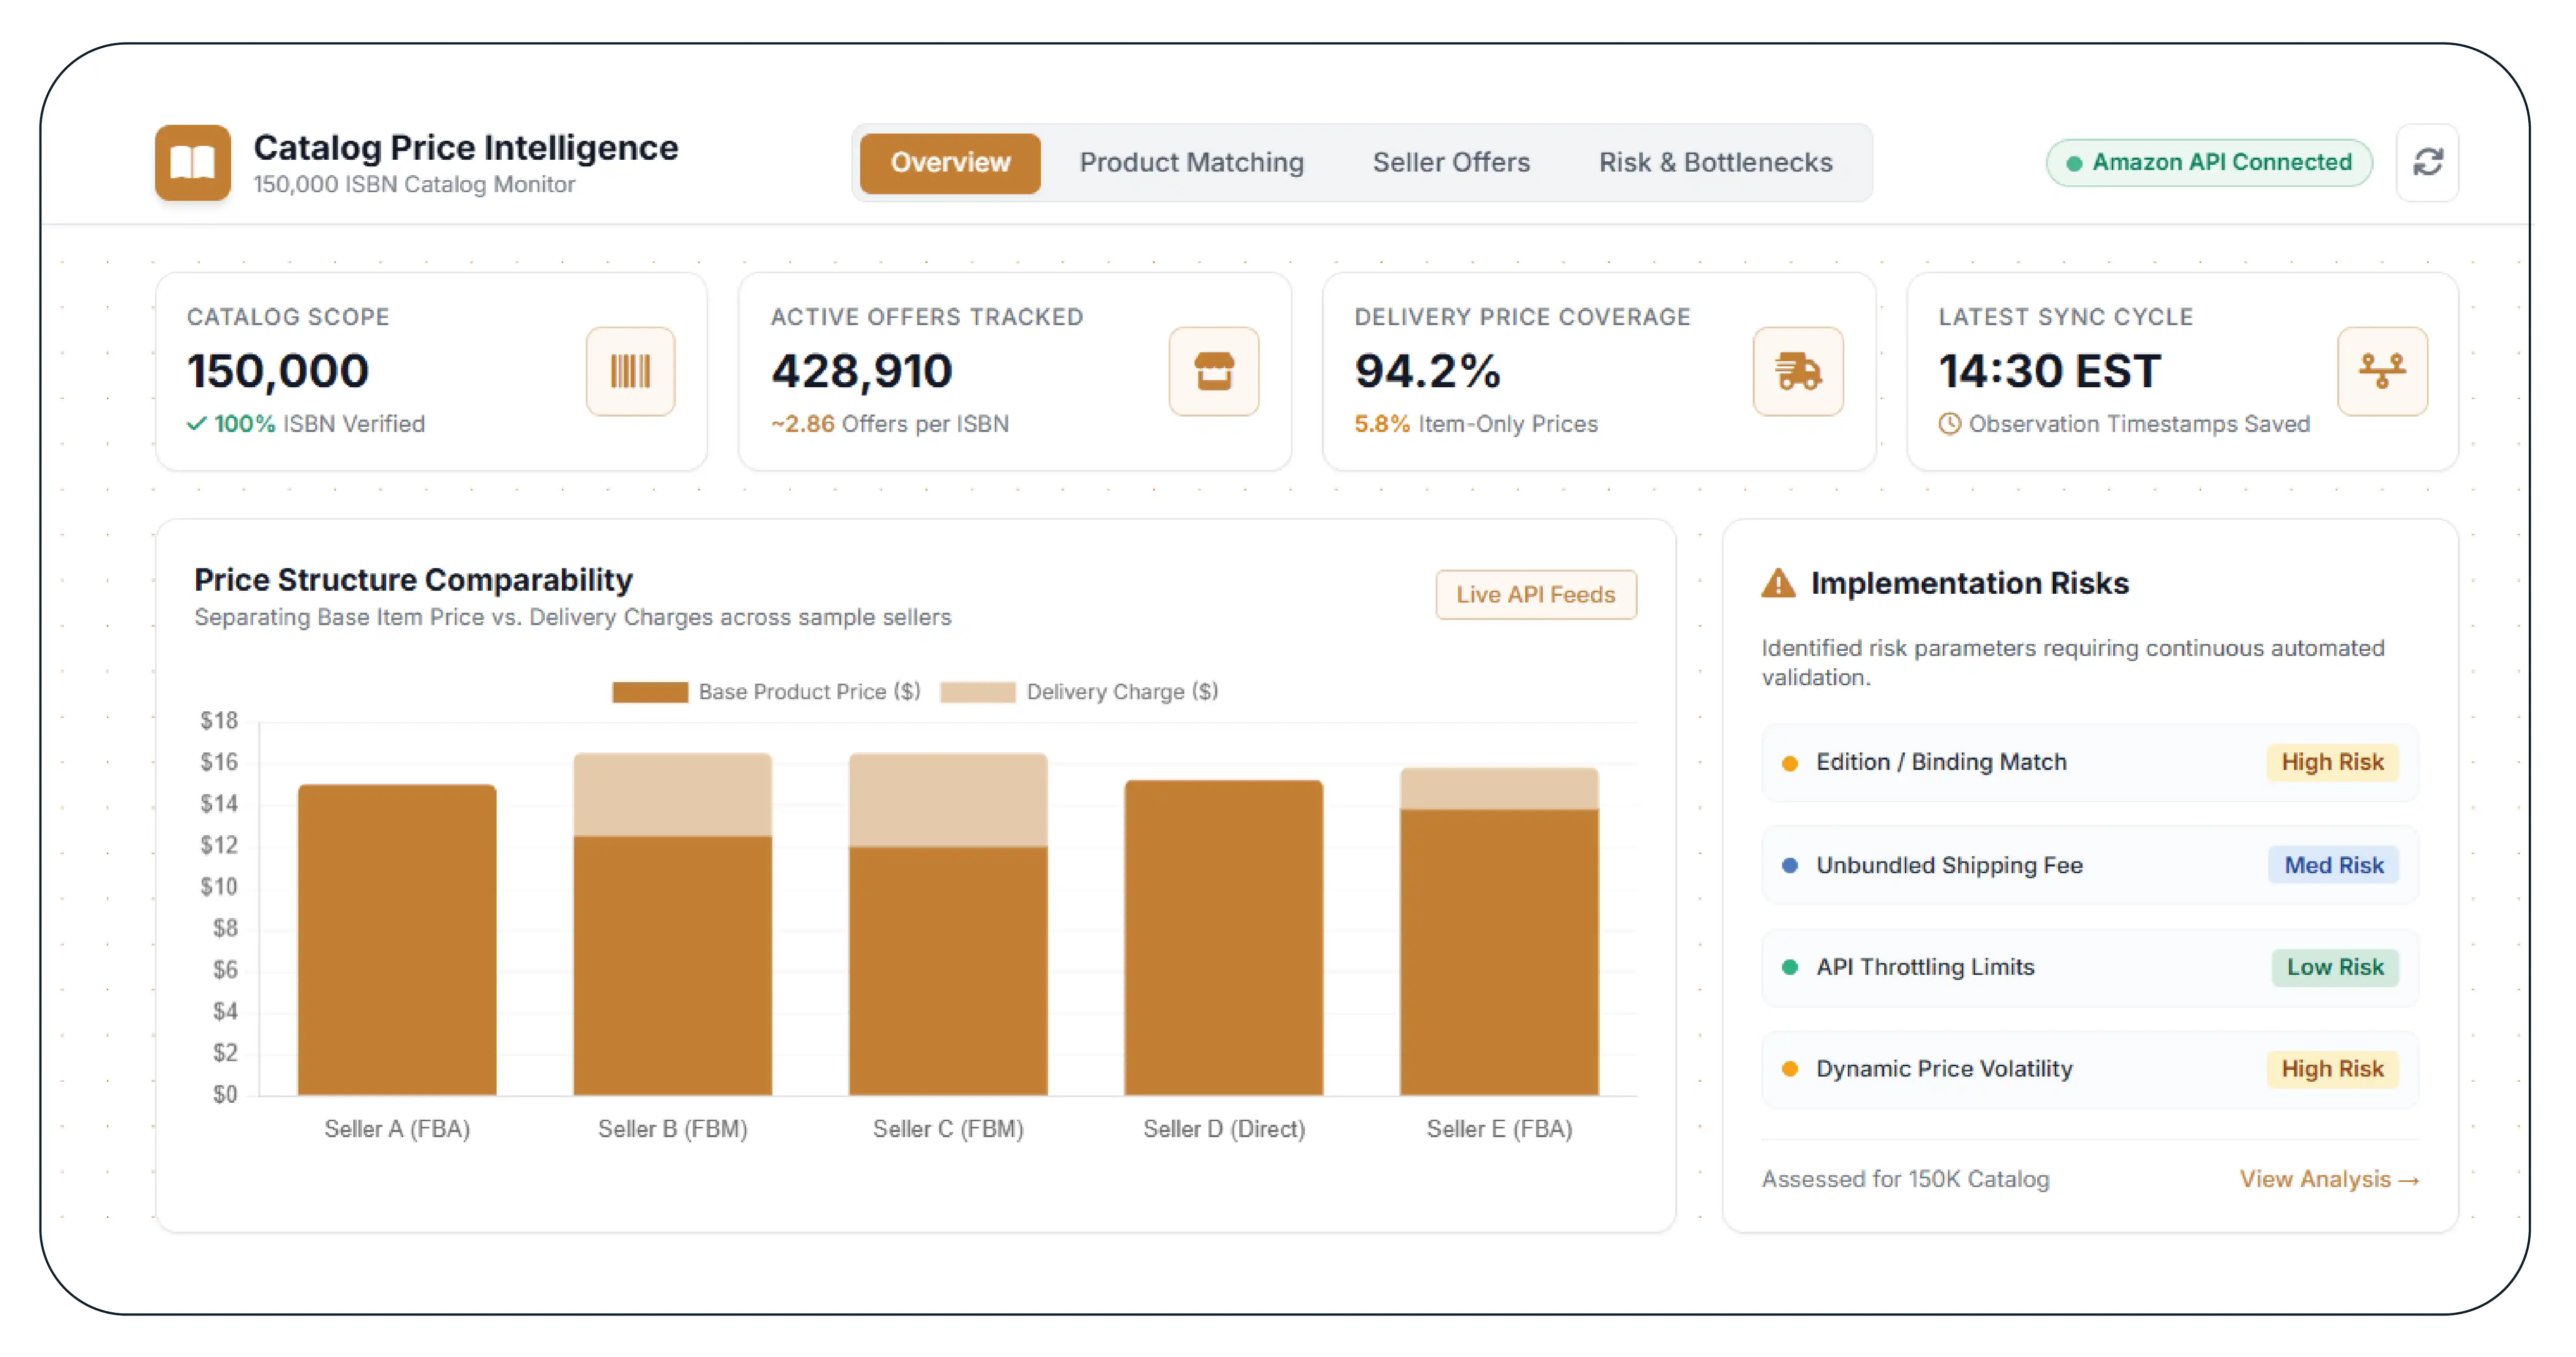
A catalog containing 150,000 ISBNs presents a substantial matching and data-management task. The main challenge is not simply collecting prices; it is ensuring that each observed offer belongs to the correct book edition and that seller-level records remain comparable.
Scrape Multiple Seller Prices for Books describes the collection requirement at the center of this project. The resulting Competitive pricing data needs consistent identifiers, seller information, price fields, and observation timestamps to support meaningful comparisons.
Several potential bottlenecks must be evaluated during implementation:
Product matching: Similar book titles may refer to different editions, publishers, bindings, or formats. ISBN-level matching helps distinguish these records.
Seller identification: A product page may display several offers, but the available seller information and offer fields can vary.
Price comparability: A displayed product price may not include delivery charges or other costs. These fields should remain separate when available.
Changing listings: Prices and availability may change between collection cycles, making timestamps essential.
Incomplete records: Missing seller names, unavailable offers, or inaccessible product pages can reduce coverage.
Validation requirements: Duplicate entries and mismatched editions can distort price comparisons if not identified.
Amazon's official pricing API documentation describes pricing and offer information for products in its catalog, including competitive pricing capabilities for eligible seller workflows. Its documented endpoints and permissions should be checked before selecting the collection method.
The project brief does not provide a verified failure rate, previous processing time, or measured data-quality problem. Accordingly, these challenges should be treated as risks to assess, not as confirmed historical failures experienced by the client.
Our Solution
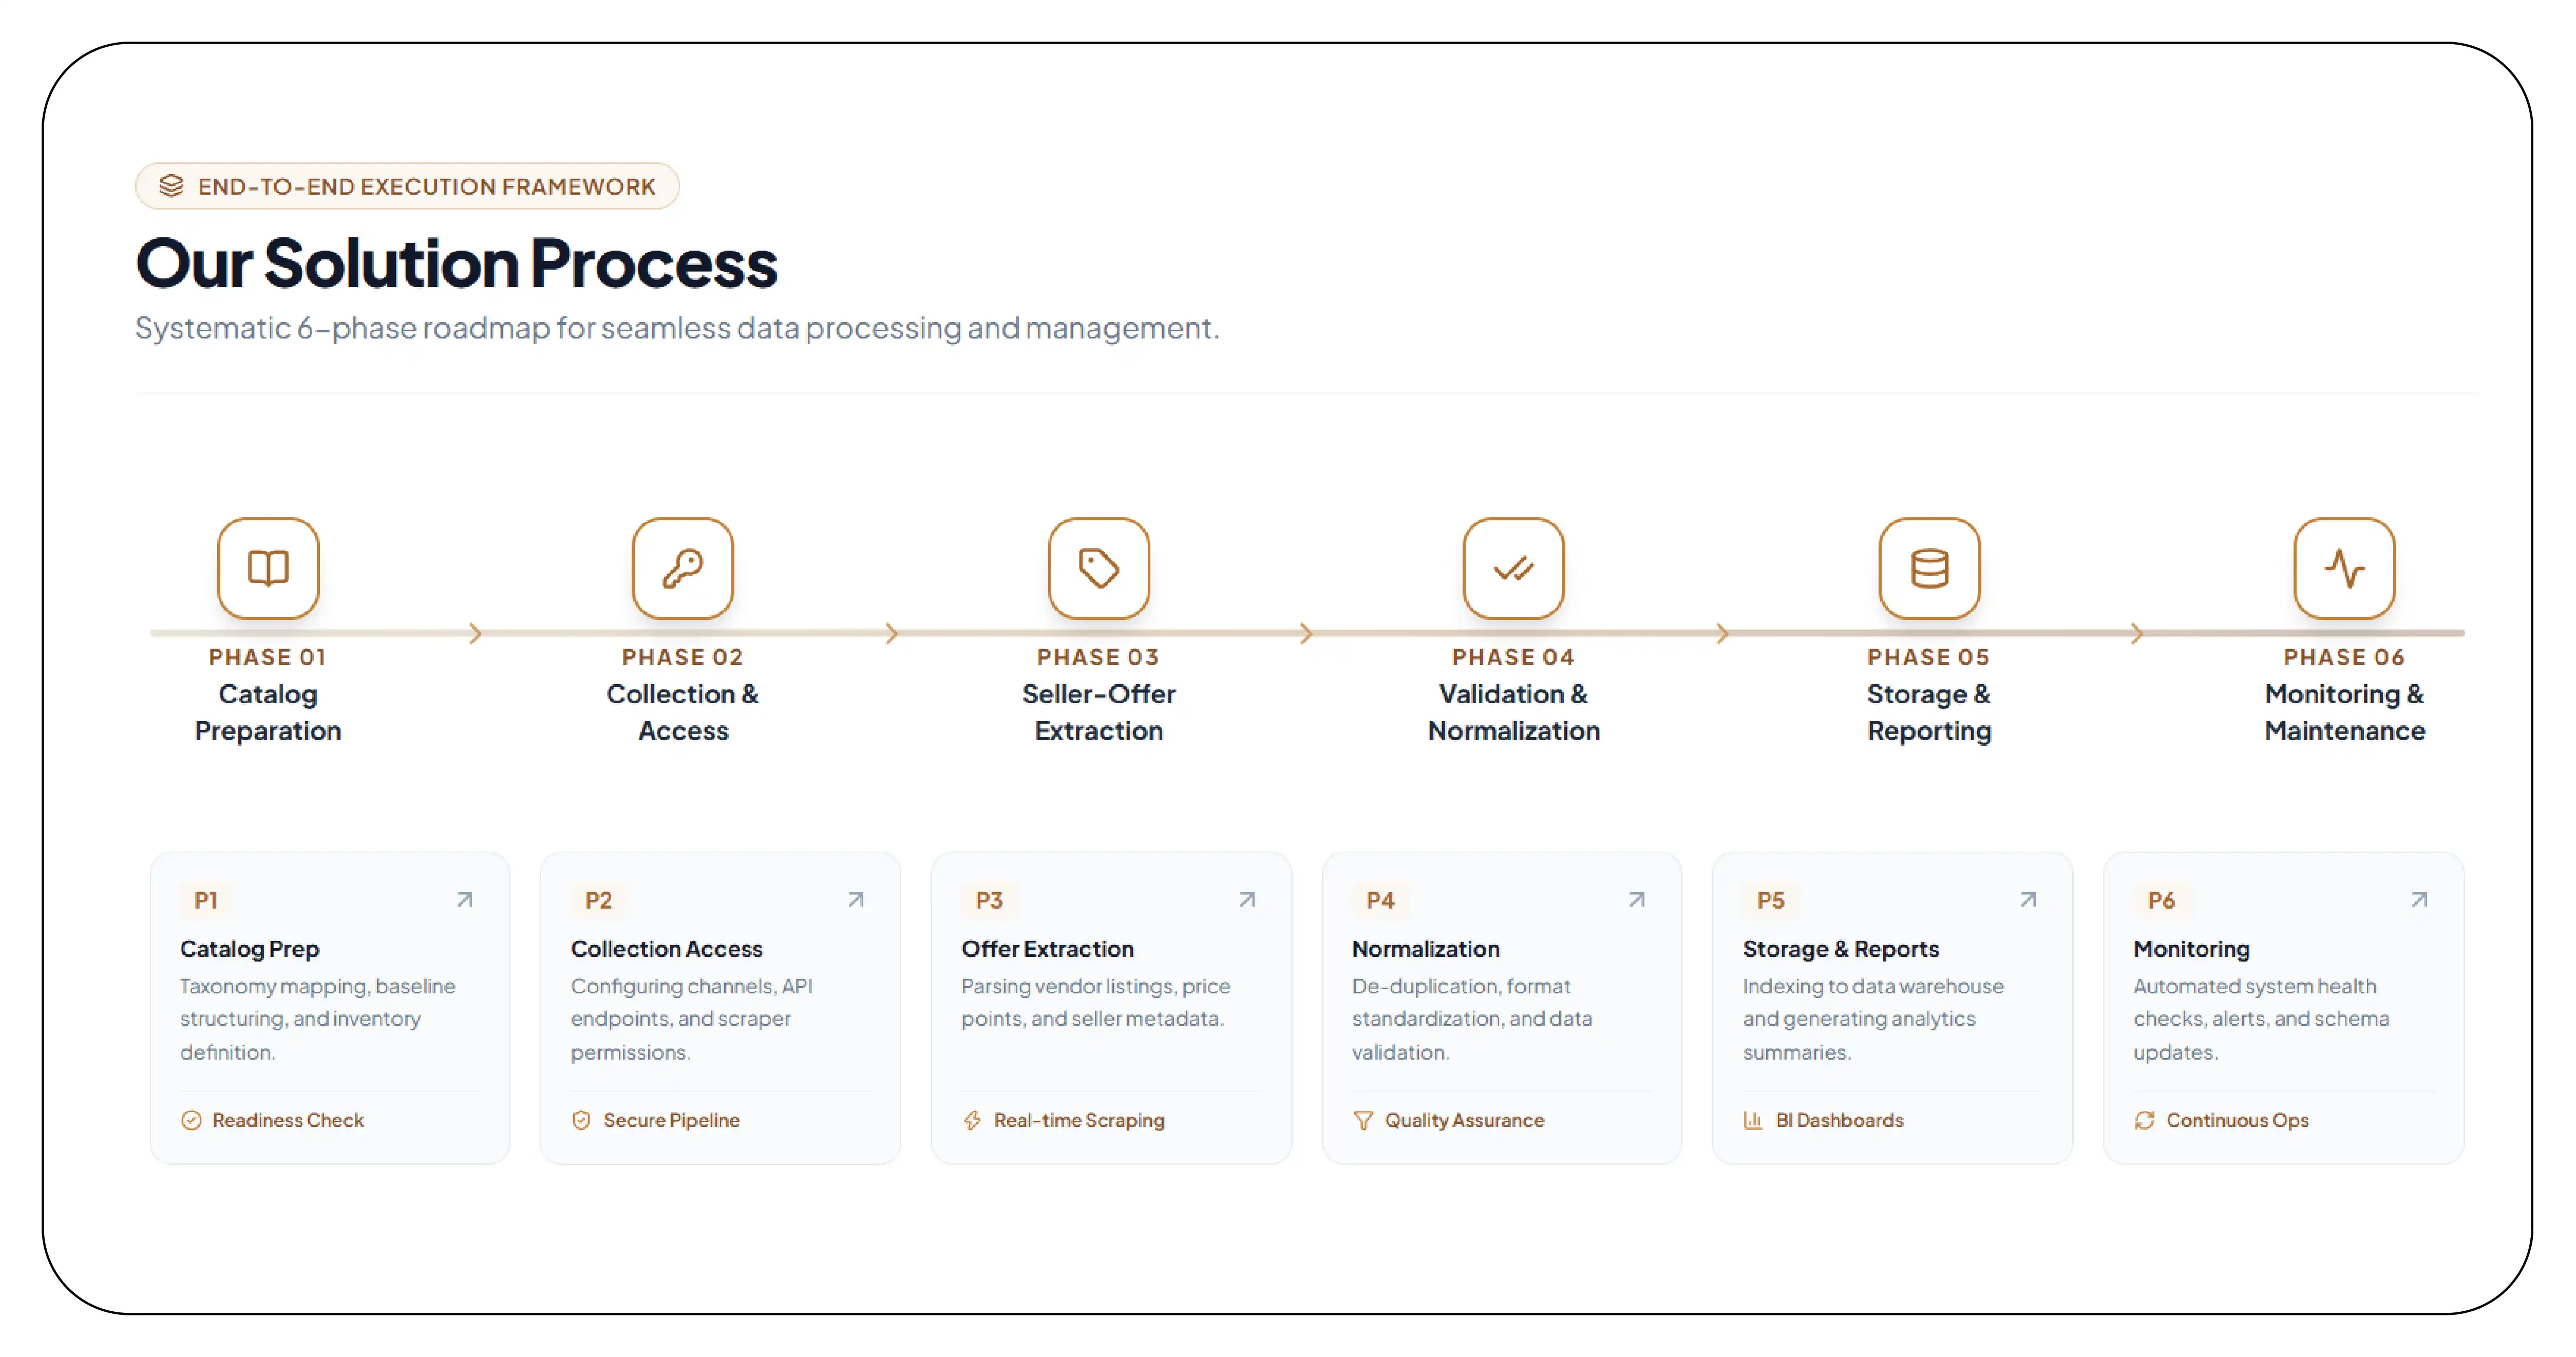
The proposed workflow for Extract Amazon ISBN Pricing for Book Distributors uses an identifier-led collection process, seller-level offer capture, and structured validation to support reliable E-commerce data for books, media. The implementation should align with the client's authorized access, the fields available from the source, and applicable platform requirements. The following phases outline the recommended approach for organizing book pricing information, matching ISBNs to the correct editions, and validating seller-level records without claiming unverified implementation details.
Phase 1: Catalog preparation
The initial stage organizes the client's 150,000 target ISBNs into a standardized input file. ISBN values are normalized, duplicate identifiers are flagged, and invalid or incomplete entries are separated for review. Where the source catalog includes titles, publishers, or formats, these fields can support subsequent quality checks. Because ISBNs identify particular editions and formats, matching should prioritize the identifier over title similarity alone.
Phase 2: Collection method and access
The team evaluates approved collection options, including Amazon's Selling Partner API where the client has the necessary permissions and the required data is available. Amazon documents API-based access to product pricing and offer information for supported seller workflows. Where another collection method is considered, its use should comply with applicable terms, permissions, and technical restrictions. Request pacing, error handling, and retry limits should be defined before large-scale processing begins.
Phase 3: Seller-offer extraction
The collection layer associates each matched book with available seller offers. Depending on source availability, the dataset may include the ISBN, title, edition details, seller name, observed price, displayed discount, shipping information, availability, product URL, and timestamp. The system then identifies the five lowest comparable offers or applies another explicitly agreed ranking rule. The selection rule must be documented: ranking by item price alone is not equivalent to ranking by total delivered price.
Phase 4: Validation and normalization
Validation checks cover ISBN formatting, duplicate offers, missing values, price formats, currency consistency, and edition matching. Records that fail checks are flagged rather than silently accepted. Prices should be retained in their observed form alongside normalized numeric values, where practical.
Phase 5: Storage and reporting
Validated records are stored in a structured dataset that supports filtering by ISBN, seller, price, and collection date. Historical snapshots enable analysts to compare observations across refresh cycles, provided the collection process consistently captures comparable fields.
Phase 6: Monitoring and maintenance
The final stage monitors collection completion, failed requests, missing records, and data freshness. Refresh schedules are based on the client's business requirements and permitted access limits. Amazon India seller data scraping is therefore best treated as a repeatable data-management workflow rather than a one-time extraction task. The final deliverables, tools, refresh frequency, and integrations must be confirmed from the actual project records before being represented as completed work.
Results and Key Metrics
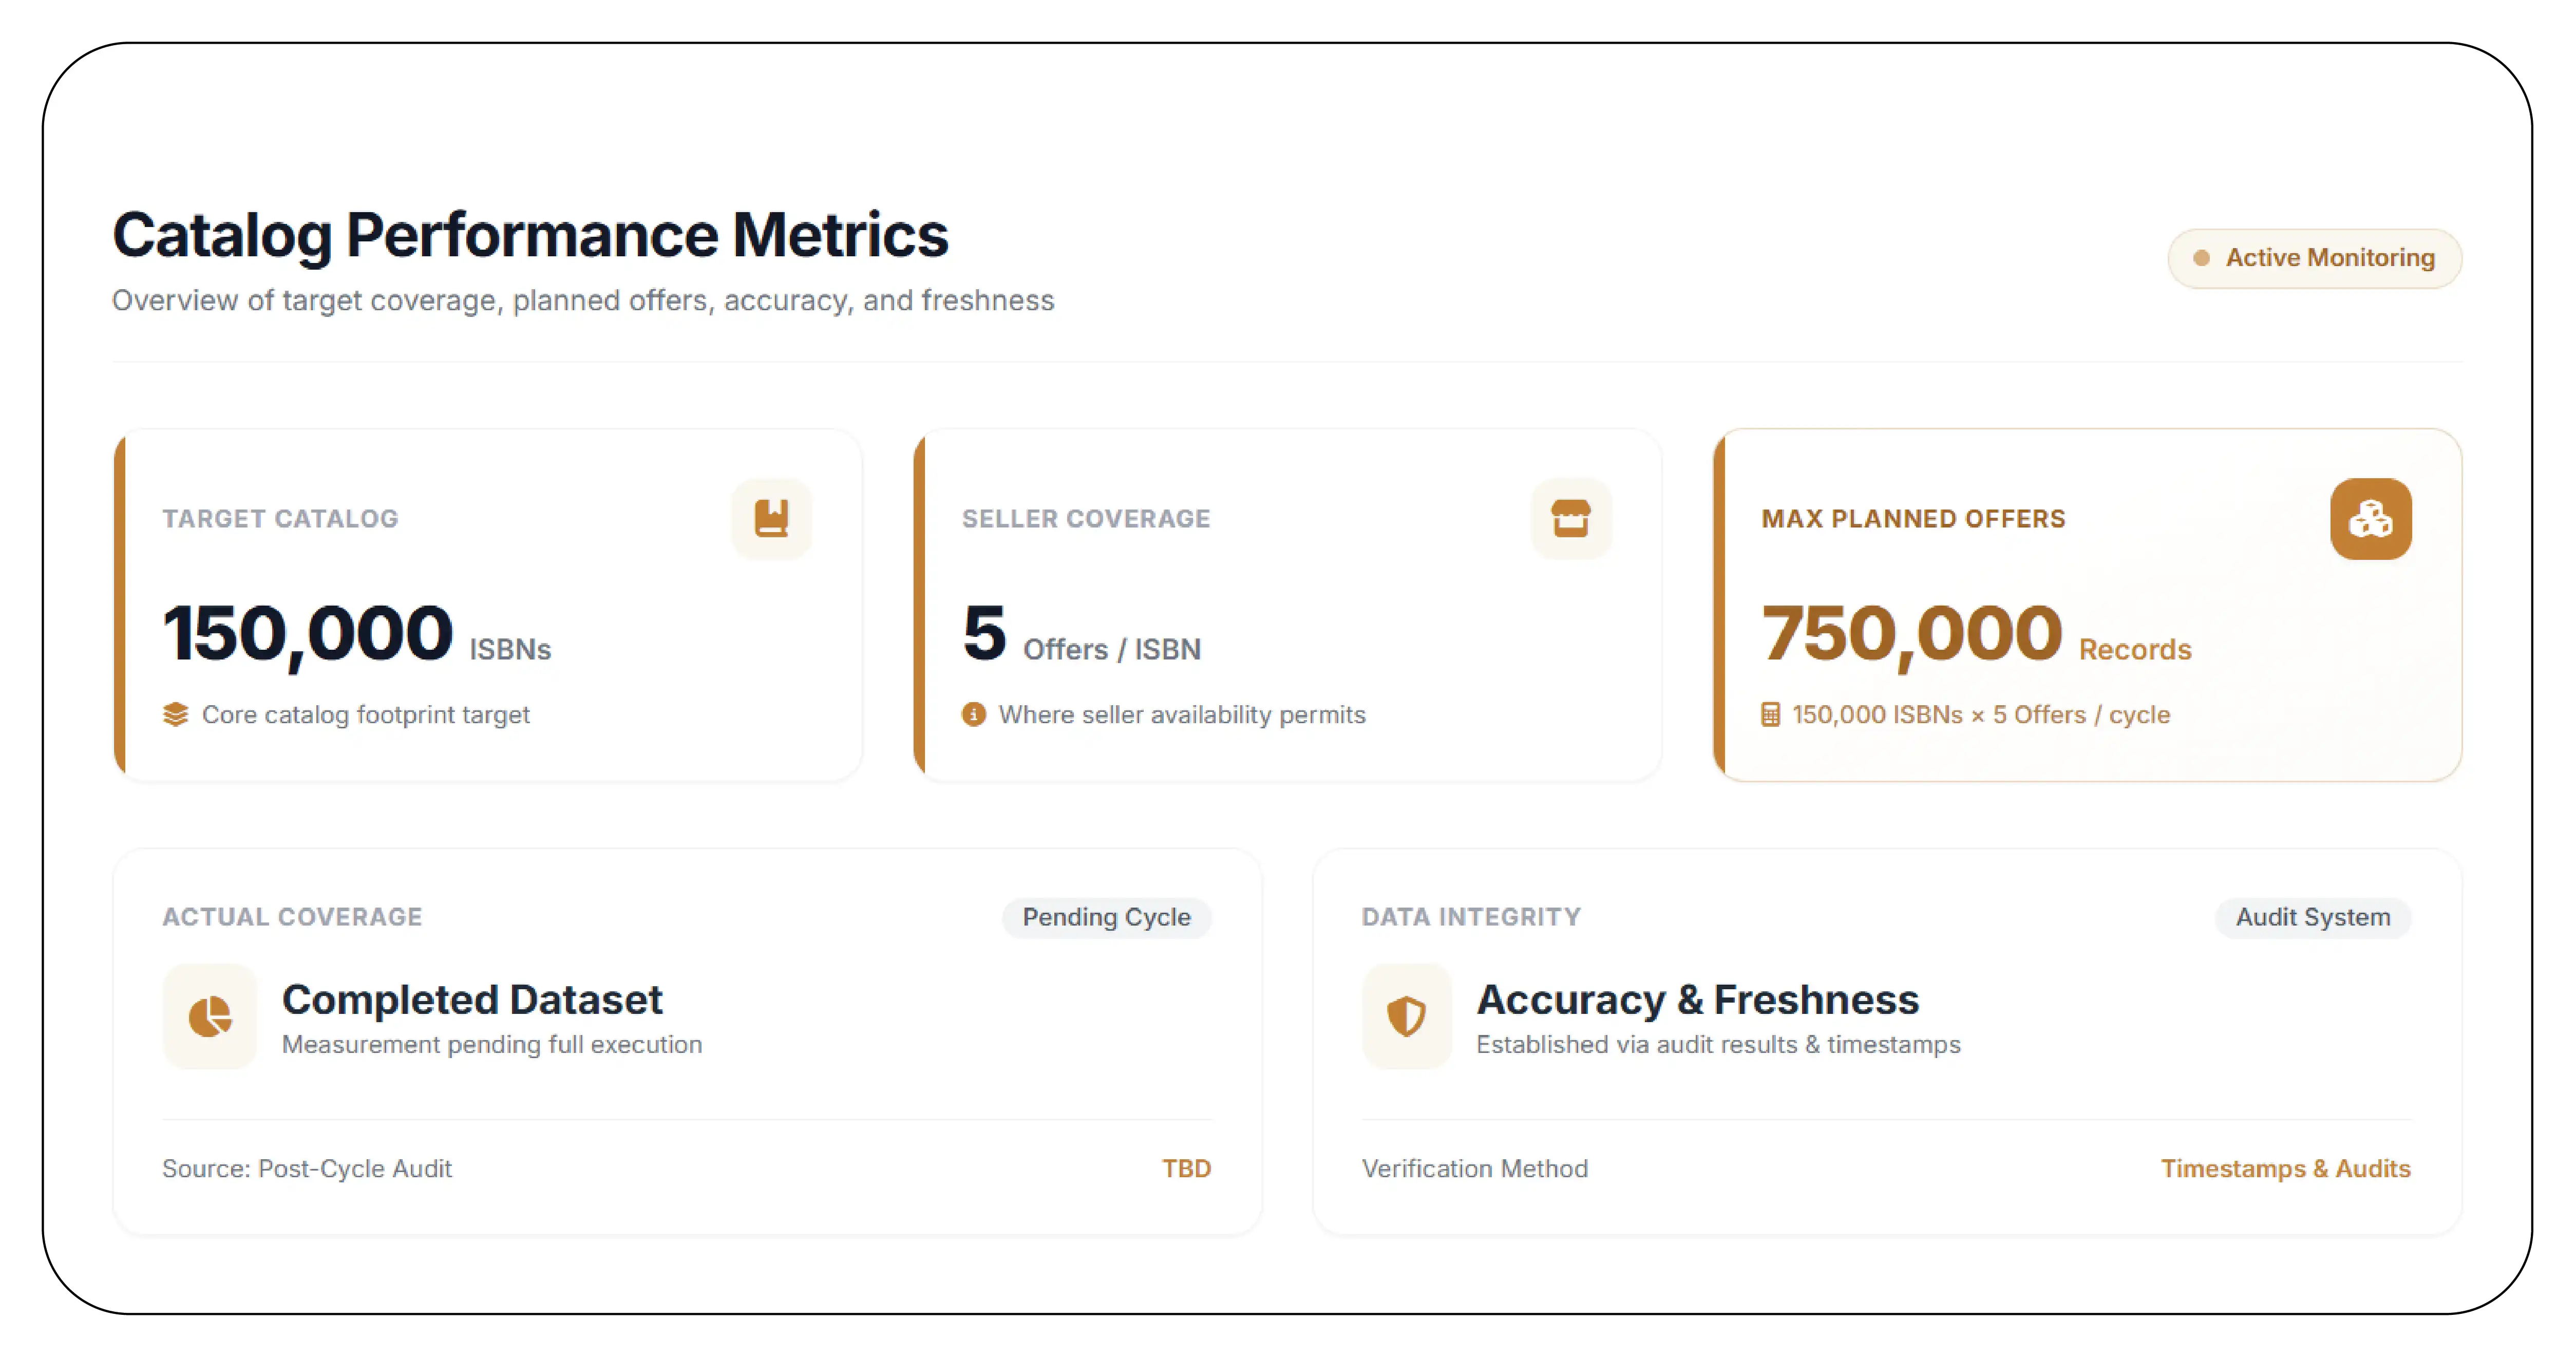
The project scope specifies 150,000 ISBNs and a target of five seller prices per ISBN. If every identifier has five valid, distinct seller offers, the resulting dataset could contain up to 750,000 ISBN–seller offer records per collection cycle. This is a calculated target, not a verified extraction result.
The reporting framework for Track Top Seller Prices on Amazon India should include:
Target catalog: 150,000 ISBNs.
Target seller coverage: Five offers per ISBN, where available.
Maximum planned offer records: 750,000 per complete cycle, calculated as 150,000 × 5.
Actual coverage: To be measured from the completed dataset.
Data accuracy and freshness: To be established through audit results and timestamps.
The project brief does not provide actual completion rates, error rates, processing times, or measured improvements. Those figures should be inserted only after validation.
Results Narrative
The intended deliverable is a structured, ISBN-linked view of seller pricing that supports comparisons across a large book catalog. Amazon India seller data scraping can support this outcome when the collection process captures available offers consistently and the resulting records pass matching and quality checks.
The key measure of success is not the volume of rows alone. Analysts should verify whether each record belongs to the correct edition, whether seller identities are distinguishable, and whether the selected offers follow the agreed price-ranking rule.
A final results report should compare baseline and post-implementation performance using audited coverage, completeness, accuracy, refresh duration, and failure rates. Until those measurements are available, no percentage improvement or operational gain can responsibly be attributed to this project.
What Made Product Data Scrape Different
A credible differentiator for Product Data Scrape is the emphasis on identifier-level matching, transparent data validation, and repeatable reporting. Amazon India Book Seller Price Scraping should be designed to distinguish separate editions, preserve original observations, and maintain traceable links between the source and the extracted record.
The proposed framework combines ISBN normalization, seller-offer ranking, duplicate detection, timestamping, and quality checks. It also separates observed data from calculated metrics so that analysts can identify which values came directly from the source and which were derived during processing.
These capabilities are design principles, not claims of proprietary technology or proven performance gains. Any specific automation framework, custom software, or integration should be named only after the technical team confirms it was used.
For the designer, a suitable visual is a dashboard showing ISBN, book title, seller, observed price, collection time, and offer rank. Use fictional interface placeholders only for design mock-ups, not as evidence of real project results.
Client's Testimonial
"Product Data Scrape helped us structure our book-pricing research across 150,000 ISBNs. The top-five seller pricing analysis provided a systematic way to compare marketplace offers, organize seller-level information, and support our competitive pricing research. Their focus on data consistency and accurate product identification was valuable for analyzing different book editions and formats."
— Head of E-commerce Operations
Conclusion
Reliable seller-price analysis begins with consistent product identification and disciplined data validation. A 150,000-ISBN research scope offers a clear foundation for examining book pricing, seller coverage, and changes in marketplace offers, provided the actual dataset supports those comparisons.
For distributors and publishing businesses, Marketplace & Seller Intelligence can help turn individual offer observations into structured information for competitive benchmarking and assortment analysis. A well-maintained collection process should preserve source references, timestamps, edition details, and clearly defined price-ranking rules.
Amazon India seller data scraping can support this objective through an appropriately authorized and validated collection workflow. The next step is to verify project performance using actual extraction logs, data-quality audits, and client-approved outcomes.
Contact Product Data Scrape to discuss a tailored book-pricing intelligence workflow for large-scale catalog research and seller comparisons.
Frequently Asked Questions
1. What is seller-price analysis for books?
It is the process of collecting and comparing available seller offers for identified book editions. ISBNs help distinguish specific editions and formats.
2. Why use ISBNs instead of book titles alone?
Titles can be similar across editions and formats. ISBNs provide a standardized identifier for matching the intended publication.
3. Can five seller prices be obtained for every ISBN?
Not necessarily. Actual coverage depends on available offers, matching quality, access permissions, and source limitations. Missing offers should be reported rather than invented.
4. Which fields should the dataset contain?
Where available, useful fields include ISBN, title, edition, seller name, observed price, shipping charge, availability, product URL, and collection timestamp.
5. How should pricing accuracy be measured?
Compare a sample of extracted records against the corresponding source observations. Measure identifier-match accuracy, price agreement, required-field completeness, duplicate rates, and data freshness.


 Singapore
 EMAIL
 PHONE






.webp)