Quick Overview
A leading FMCG and grocery brand needed a scalable way to understand product availability across Blinkit's rapidly changing quick-commerce network. Product Data Scrape implemented Blinkit Product Availability Tracking Across 50+ Locations to create location-level visibility into product presence, stock status, rankings, and listing information. The project also enabled the brand to Extract Blinkit Q-Commerce Data through a structured, recurring workflow.
Client Name / Industry: Leading FMCG & Grocery Consumer Brand.
Service / Duration: Blinkit product and availability data collection / Recurring monitoring engagement.
Key Impact Metrics: 50+ locations monitored, SKU-level availability tracking, and automated recurring data collection. The resulting dataset gave business teams a more consistent foundation for distribution, merchandising, and availability analysis.
The Client
The client was a consumer-facing FMCG and grocery brand operating in a highly competitive quick-commerce environment. Its products were distributed through digital platforms where assortment, visibility, rankings, and availability could change by location and time.
Quick commerce has increased the importance of digital shelf visibility. Consumers increasingly expect grocery and everyday products to be available for rapid delivery, while brands need to understand whether their products can actually be discovered and purchased in individual service areas.
The client's previous monitoring process relied heavily on manual checks and fragmented observations. Teams could review selected products and locations, but maintaining a consistent picture across more than 50 locations became difficult. Availability could change during the day, while product listings and rankings could also vary by service area.
The business therefore required grocery product stock monitoring across cities rather than isolated checks. It also wanted broader visibility that could support comparisons with Global quick commerce data, particularly as quick-commerce models continued expanding across markets.
The transformation was important because a product being listed nationally did not necessarily mean it was available to customers in every location. The brand needed structured, repeatable observations that could identify location-level gaps and provide historical context for commercial teams.
Goals & Objectives
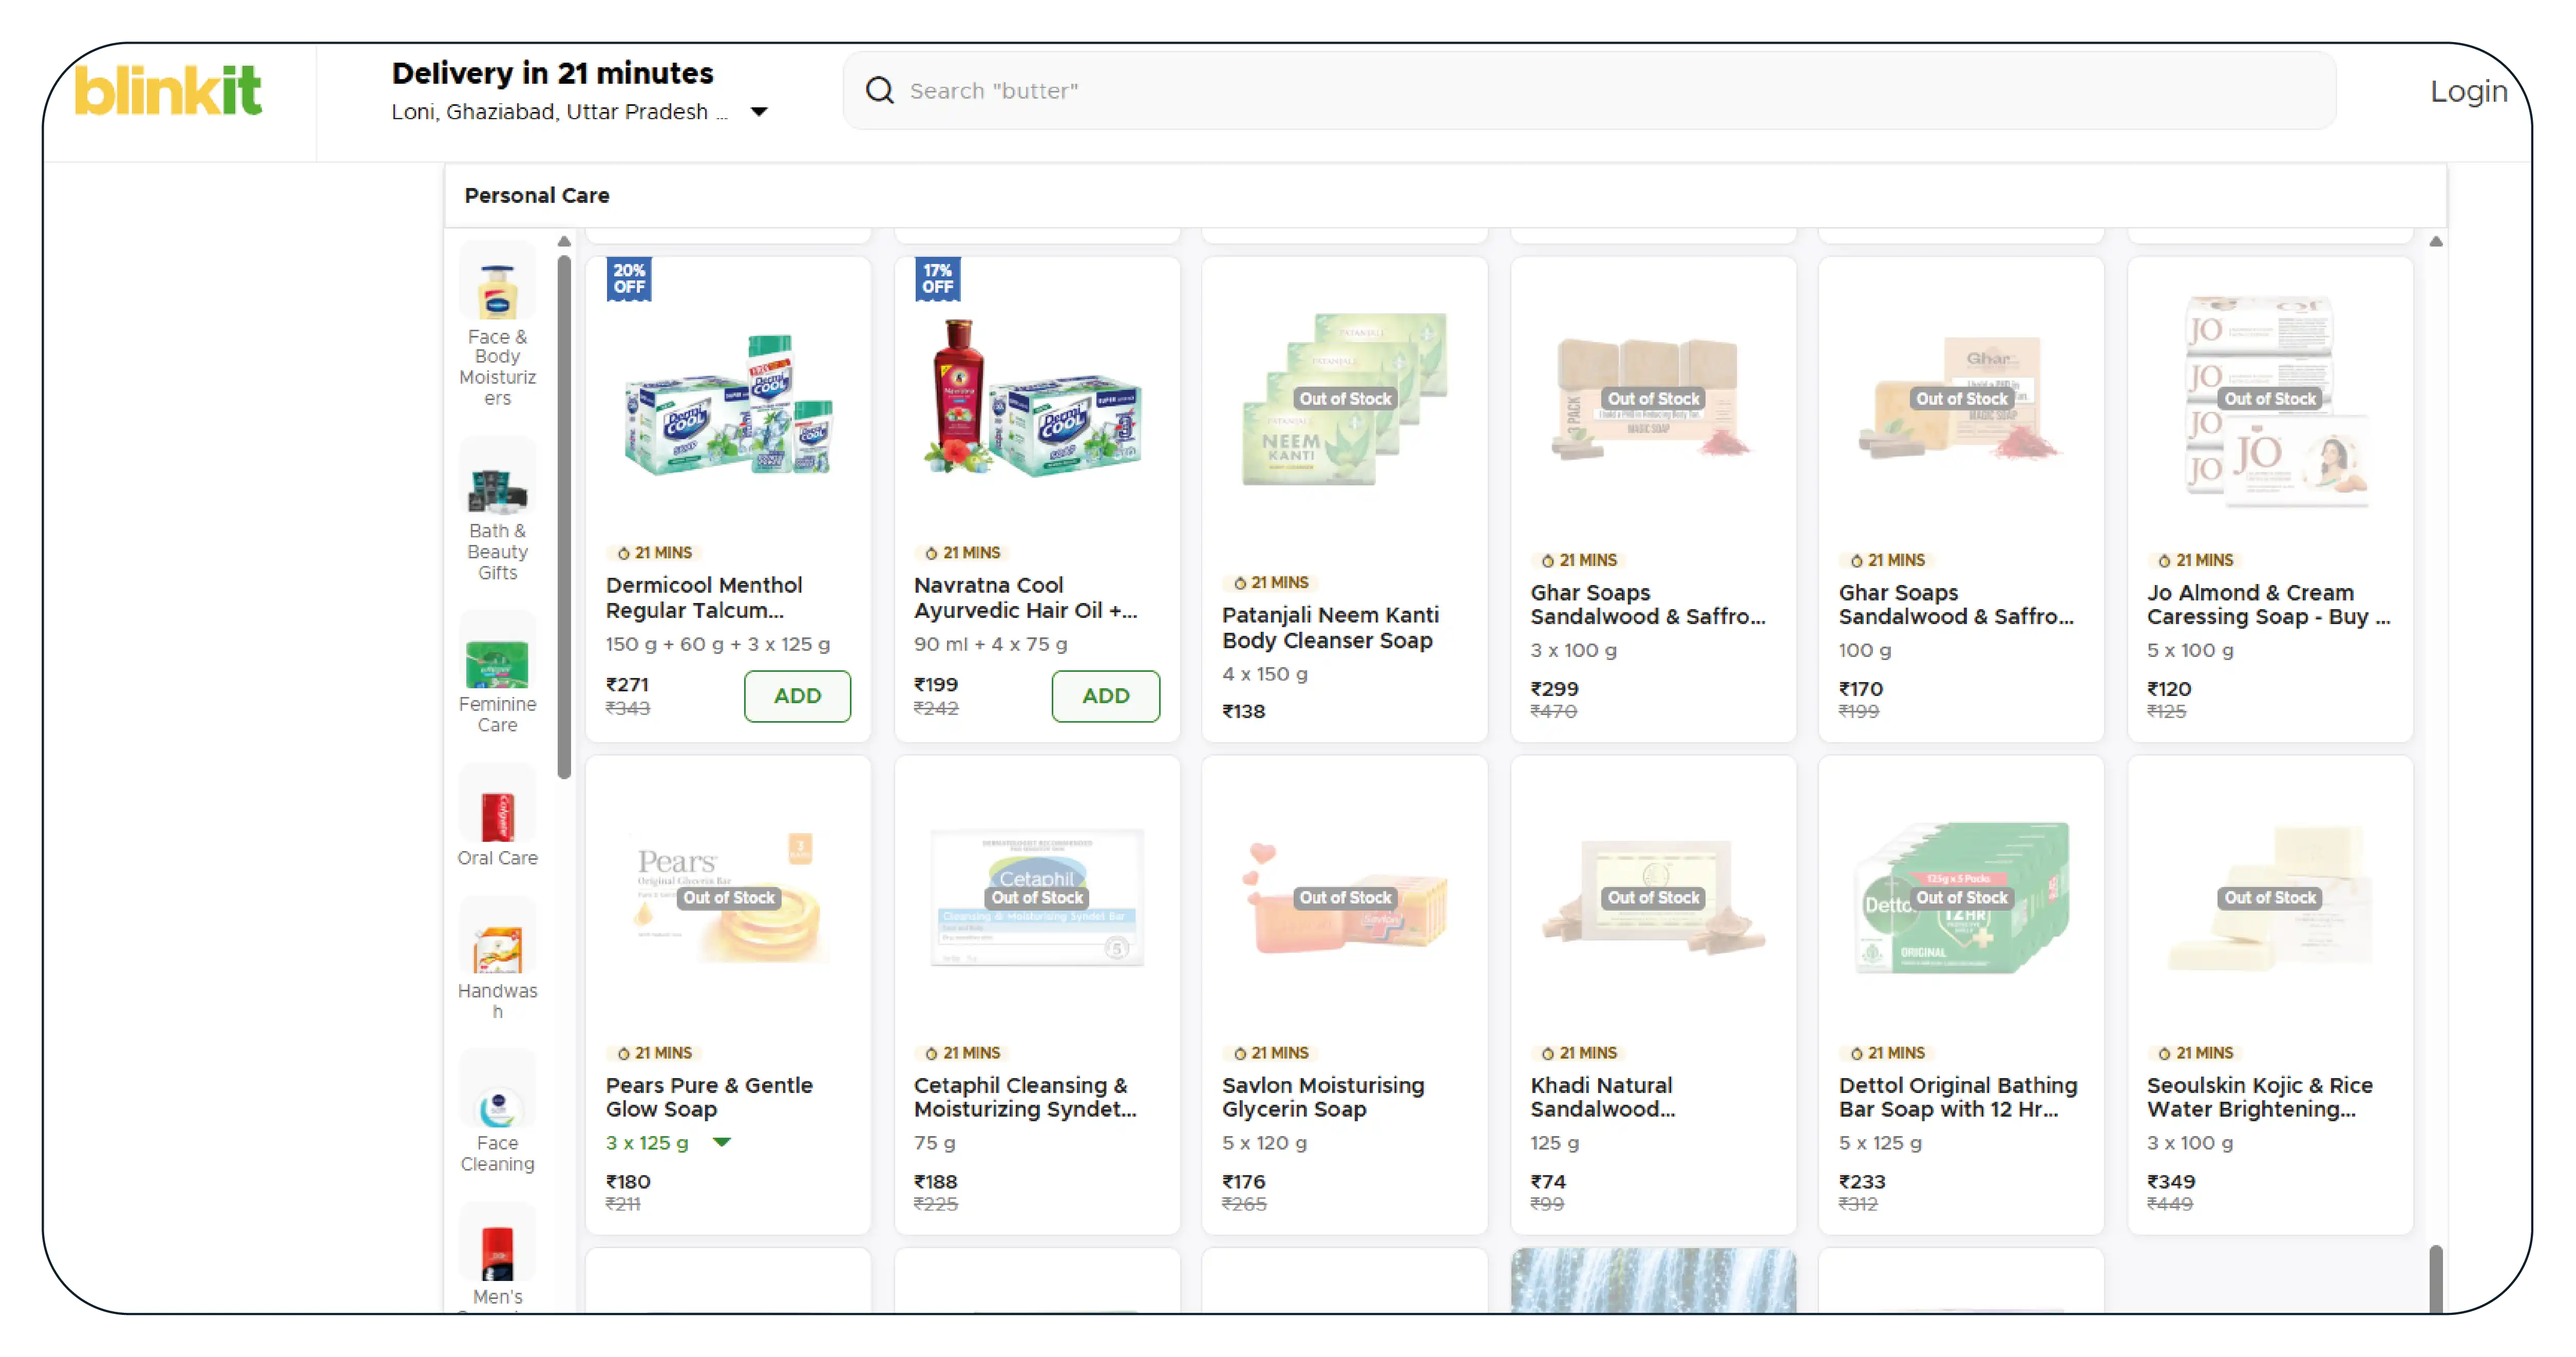
The primary business goal was to create a scalable monitoring framework that could provide consistent product visibility across 50+ Blinkit locations.
Improve scalability across locations and SKUs.
Reduce dependence on manual availability checks.
Improve the speed of identifying stock-status changes.
Increase consistency and accuracy of collected product records.
Support merchandising and distribution teams with structured insights.
Establish a repeatable monitoring process for expanding location coverage.
The technical implementation focused on automating collection and organizing the output for downstream analysis.
Automate recurring collection of Blinkit product ranking and availability data.
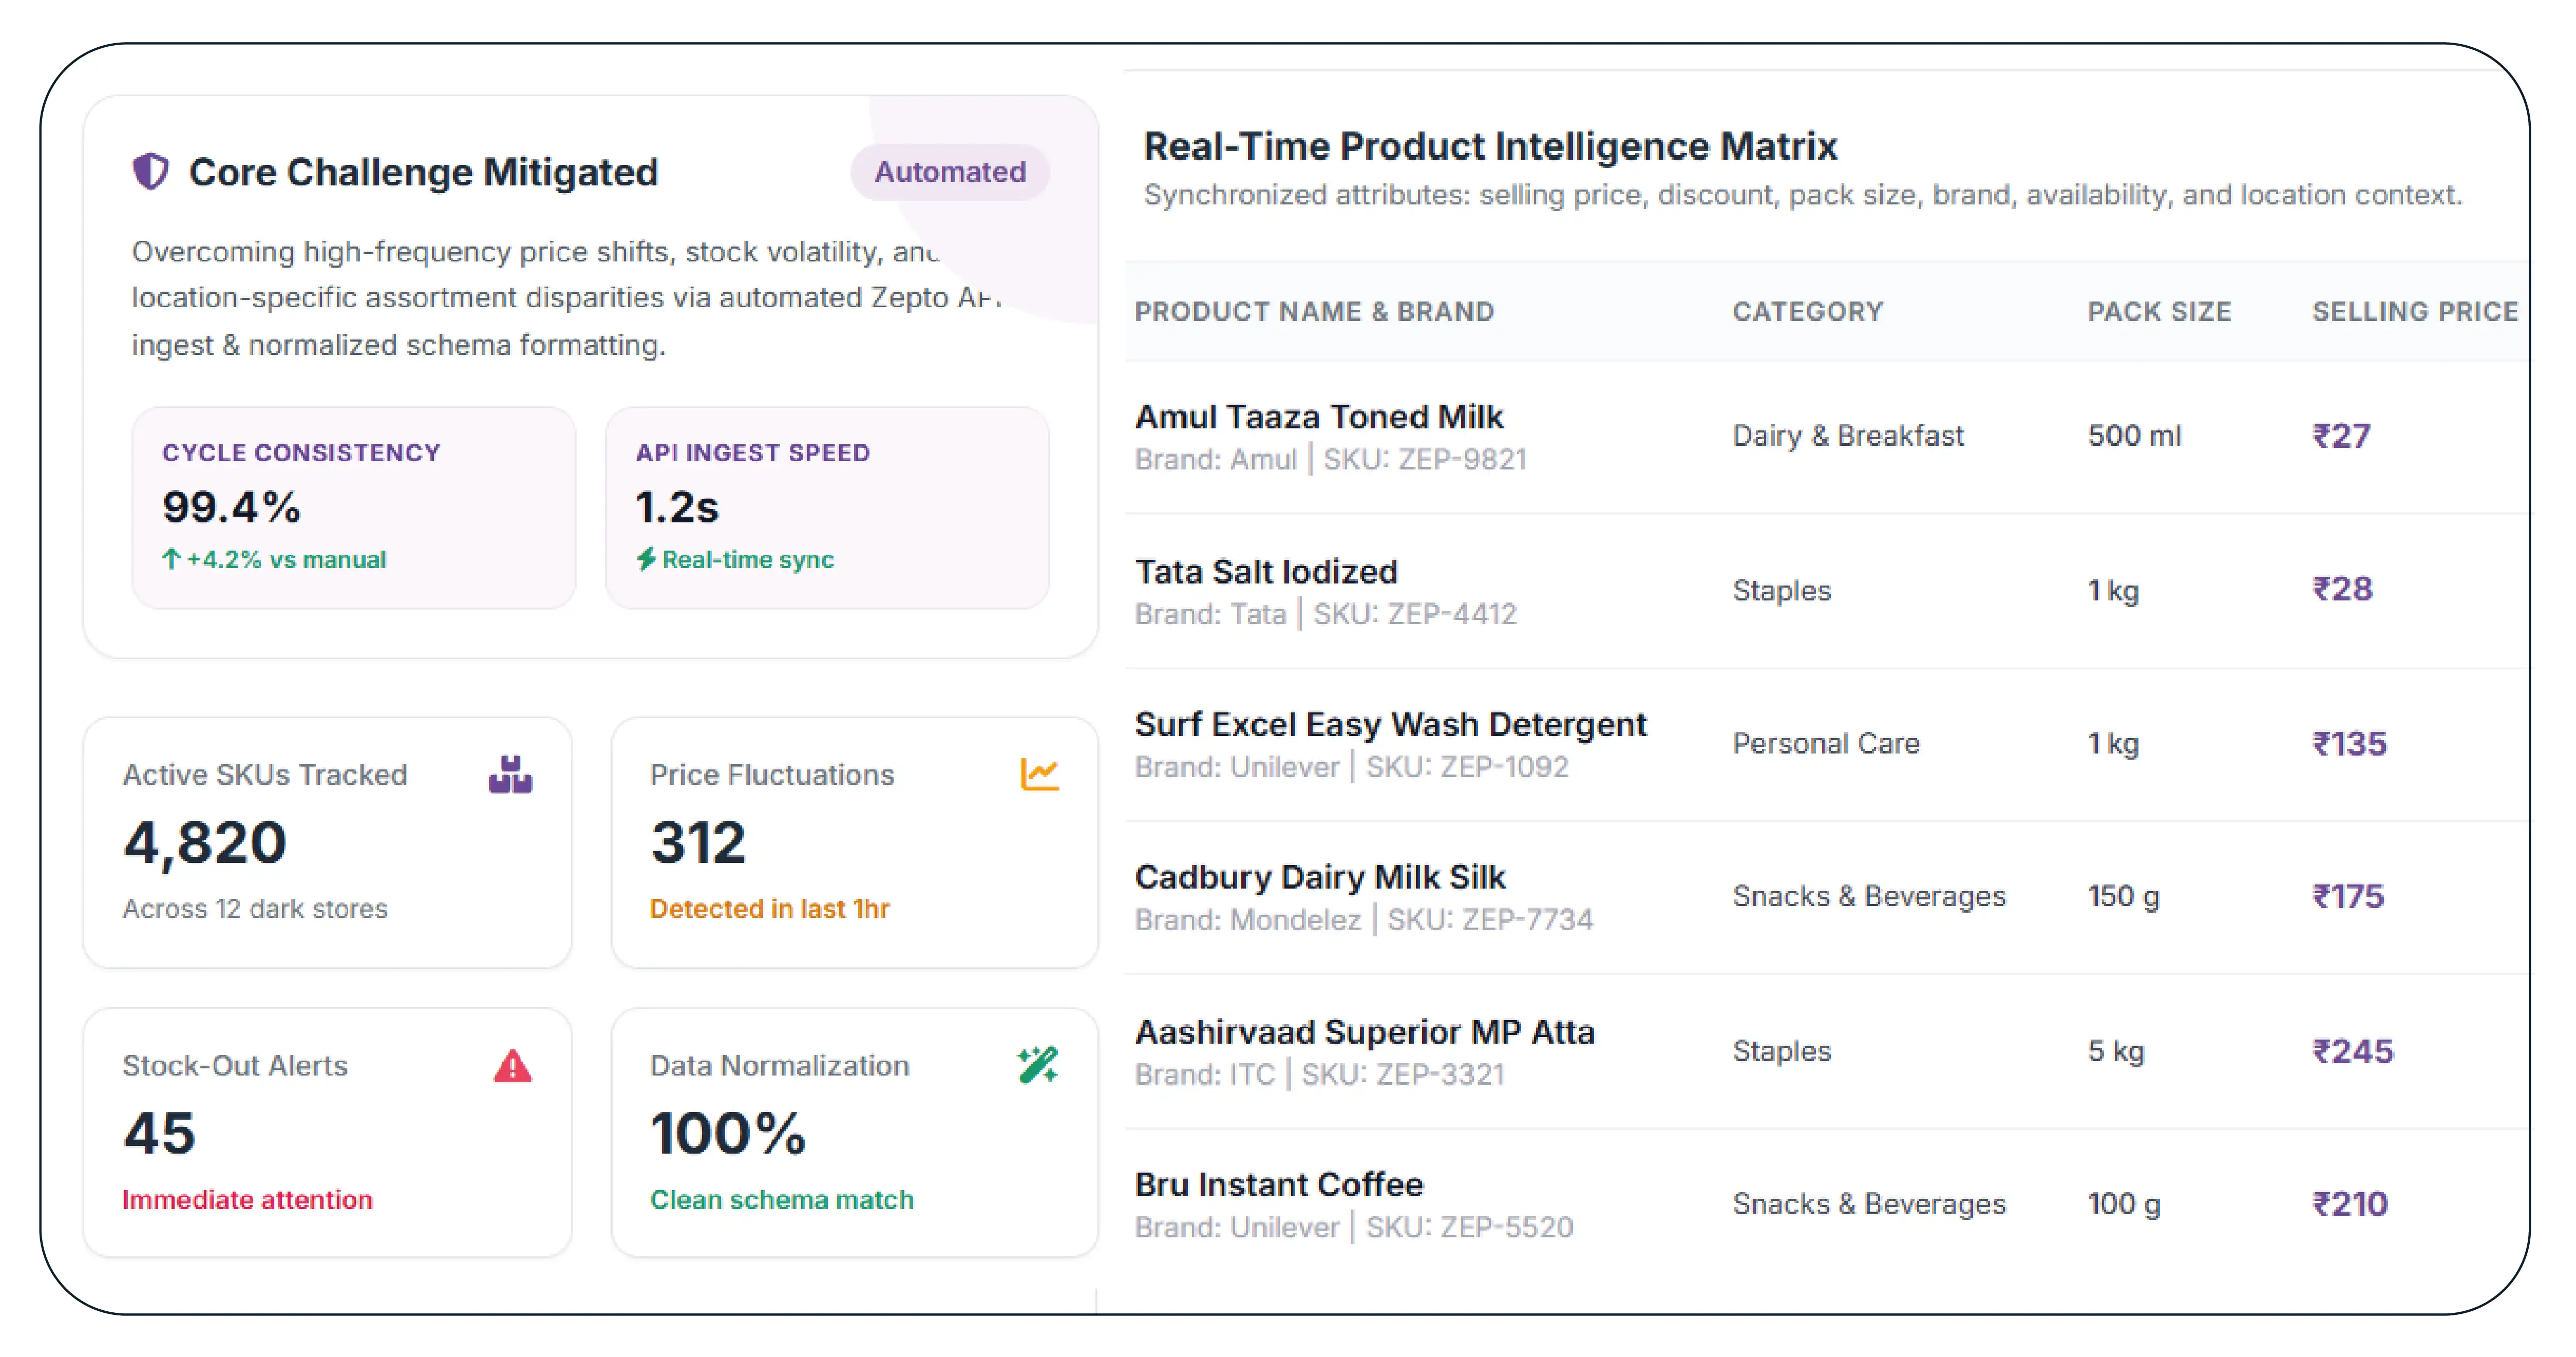
Build a structured Blinkit grocery dataset with SKU, product, location, availability, and timestamp fields.
Normalize product names, categories, pack sizes, and availability statuses.
Maintain historical snapshots for change detection.
Enable integration with internal analytics workflows.
Create outputs suitable for dashboards, databases, and recurring reporting.
Establish validation rules for missing, duplicate, or inconsistent records.
The project KPIs were designed around operational performance rather than cost savings:
50+ locations included in recurring monitoring.
SKU-level availability captured consistently.
Automated recurring collection instead of manual location-by-location checks.
Historical availability records maintained for comparison.
Location-level stock changes surfaced through structured data.
Improved data consistency through normalization and validation.
The Core Challenge
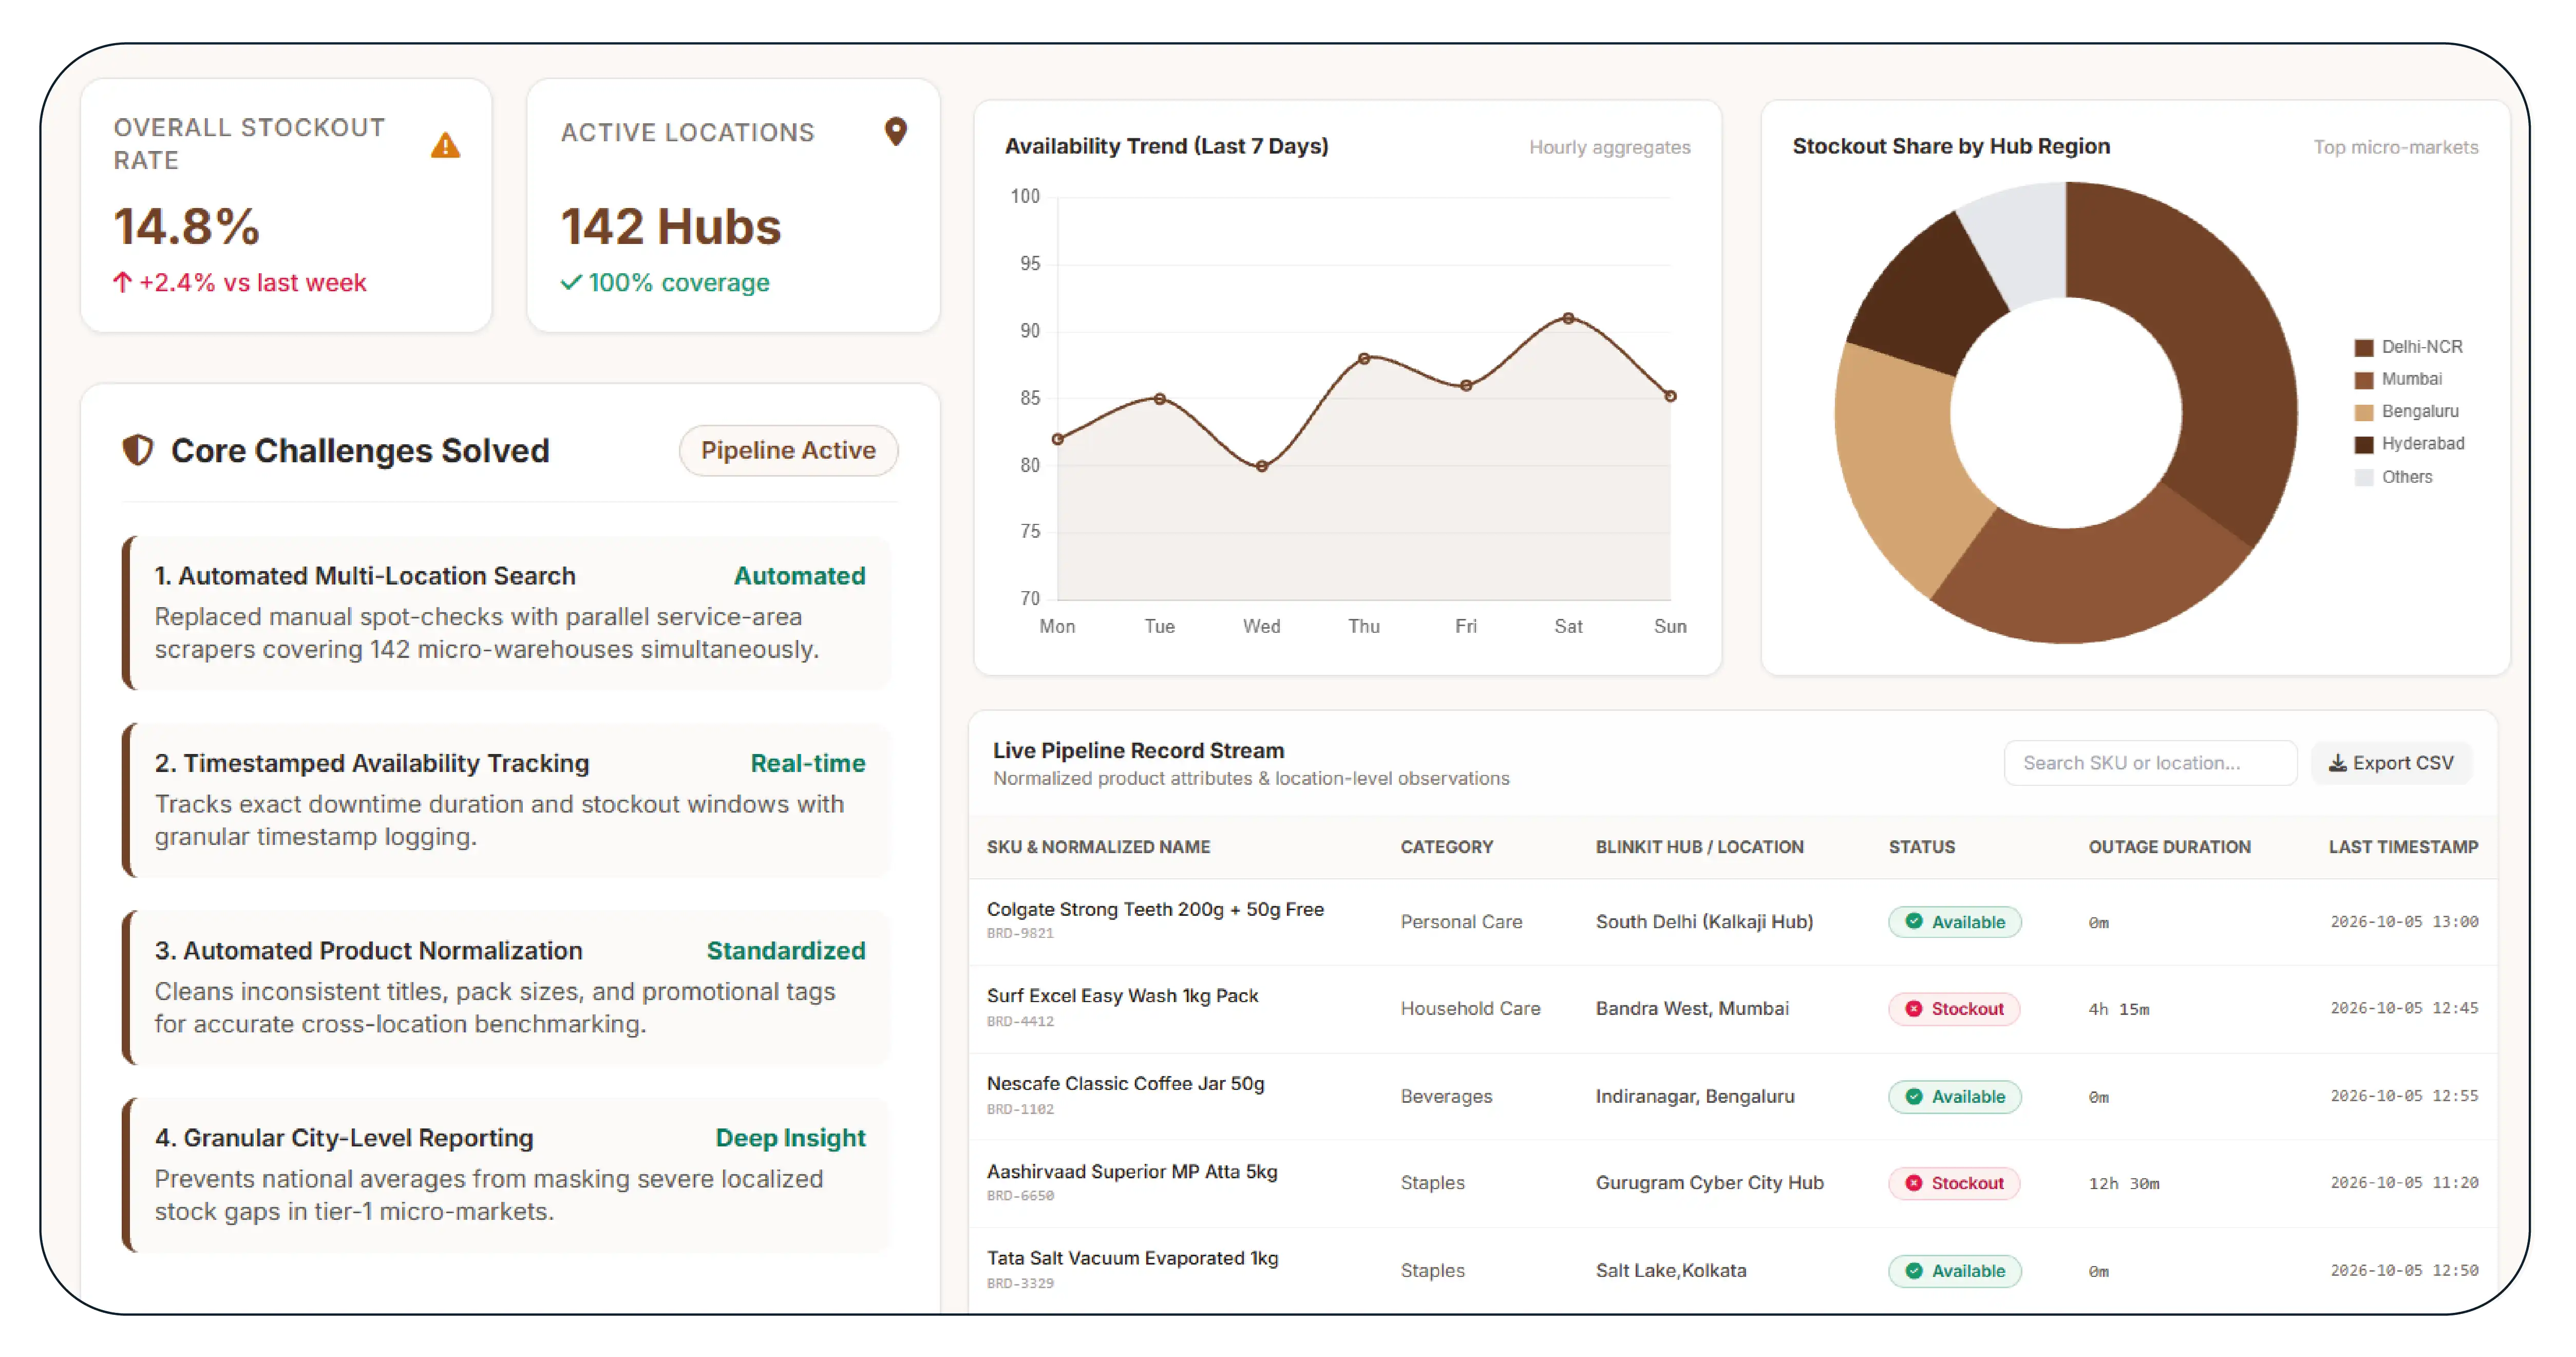
The client's biggest challenge was the fragmented nature of quick-commerce availability. A product could appear available in one Blinkit service area while being unavailable in another. Monitoring a handful of locations manually did not provide enough coverage to identify the full pattern.
The project involved FMCG brand monitoring across Blinkit locations, with multiple operational bottlenecks affecting the previous workflow.
First, manual checks required teams to repeatedly search products across locations. This consumed analyst time and made it difficult to maintain a consistent monitoring frequency.
Second, availability was dynamic. A product observed as available during one check could become unavailable later. Without timestamped records, teams could not determine when a status changed or how long an availability gap persisted.
Third, product information was not always uniform. Product names, pack sizes, categories, promotional information, and listing attributes could require normalization before meaningful comparisons could be performed.
Fourth, location-level differences complicated reporting. A national-level availability percentage could hide serious gaps in specific cities or service areas.
Finally, the business needed historical data. A one-time snapshot could show current availability but could not reveal recurring stockouts, frequently affected locations, or changes in product visibility.
The challenge was therefore not simply collecting product pages. It was creating a repeatable data pipeline capable of converting changing location-level observations into structured, comparable, and historically useful records.
Our Solution
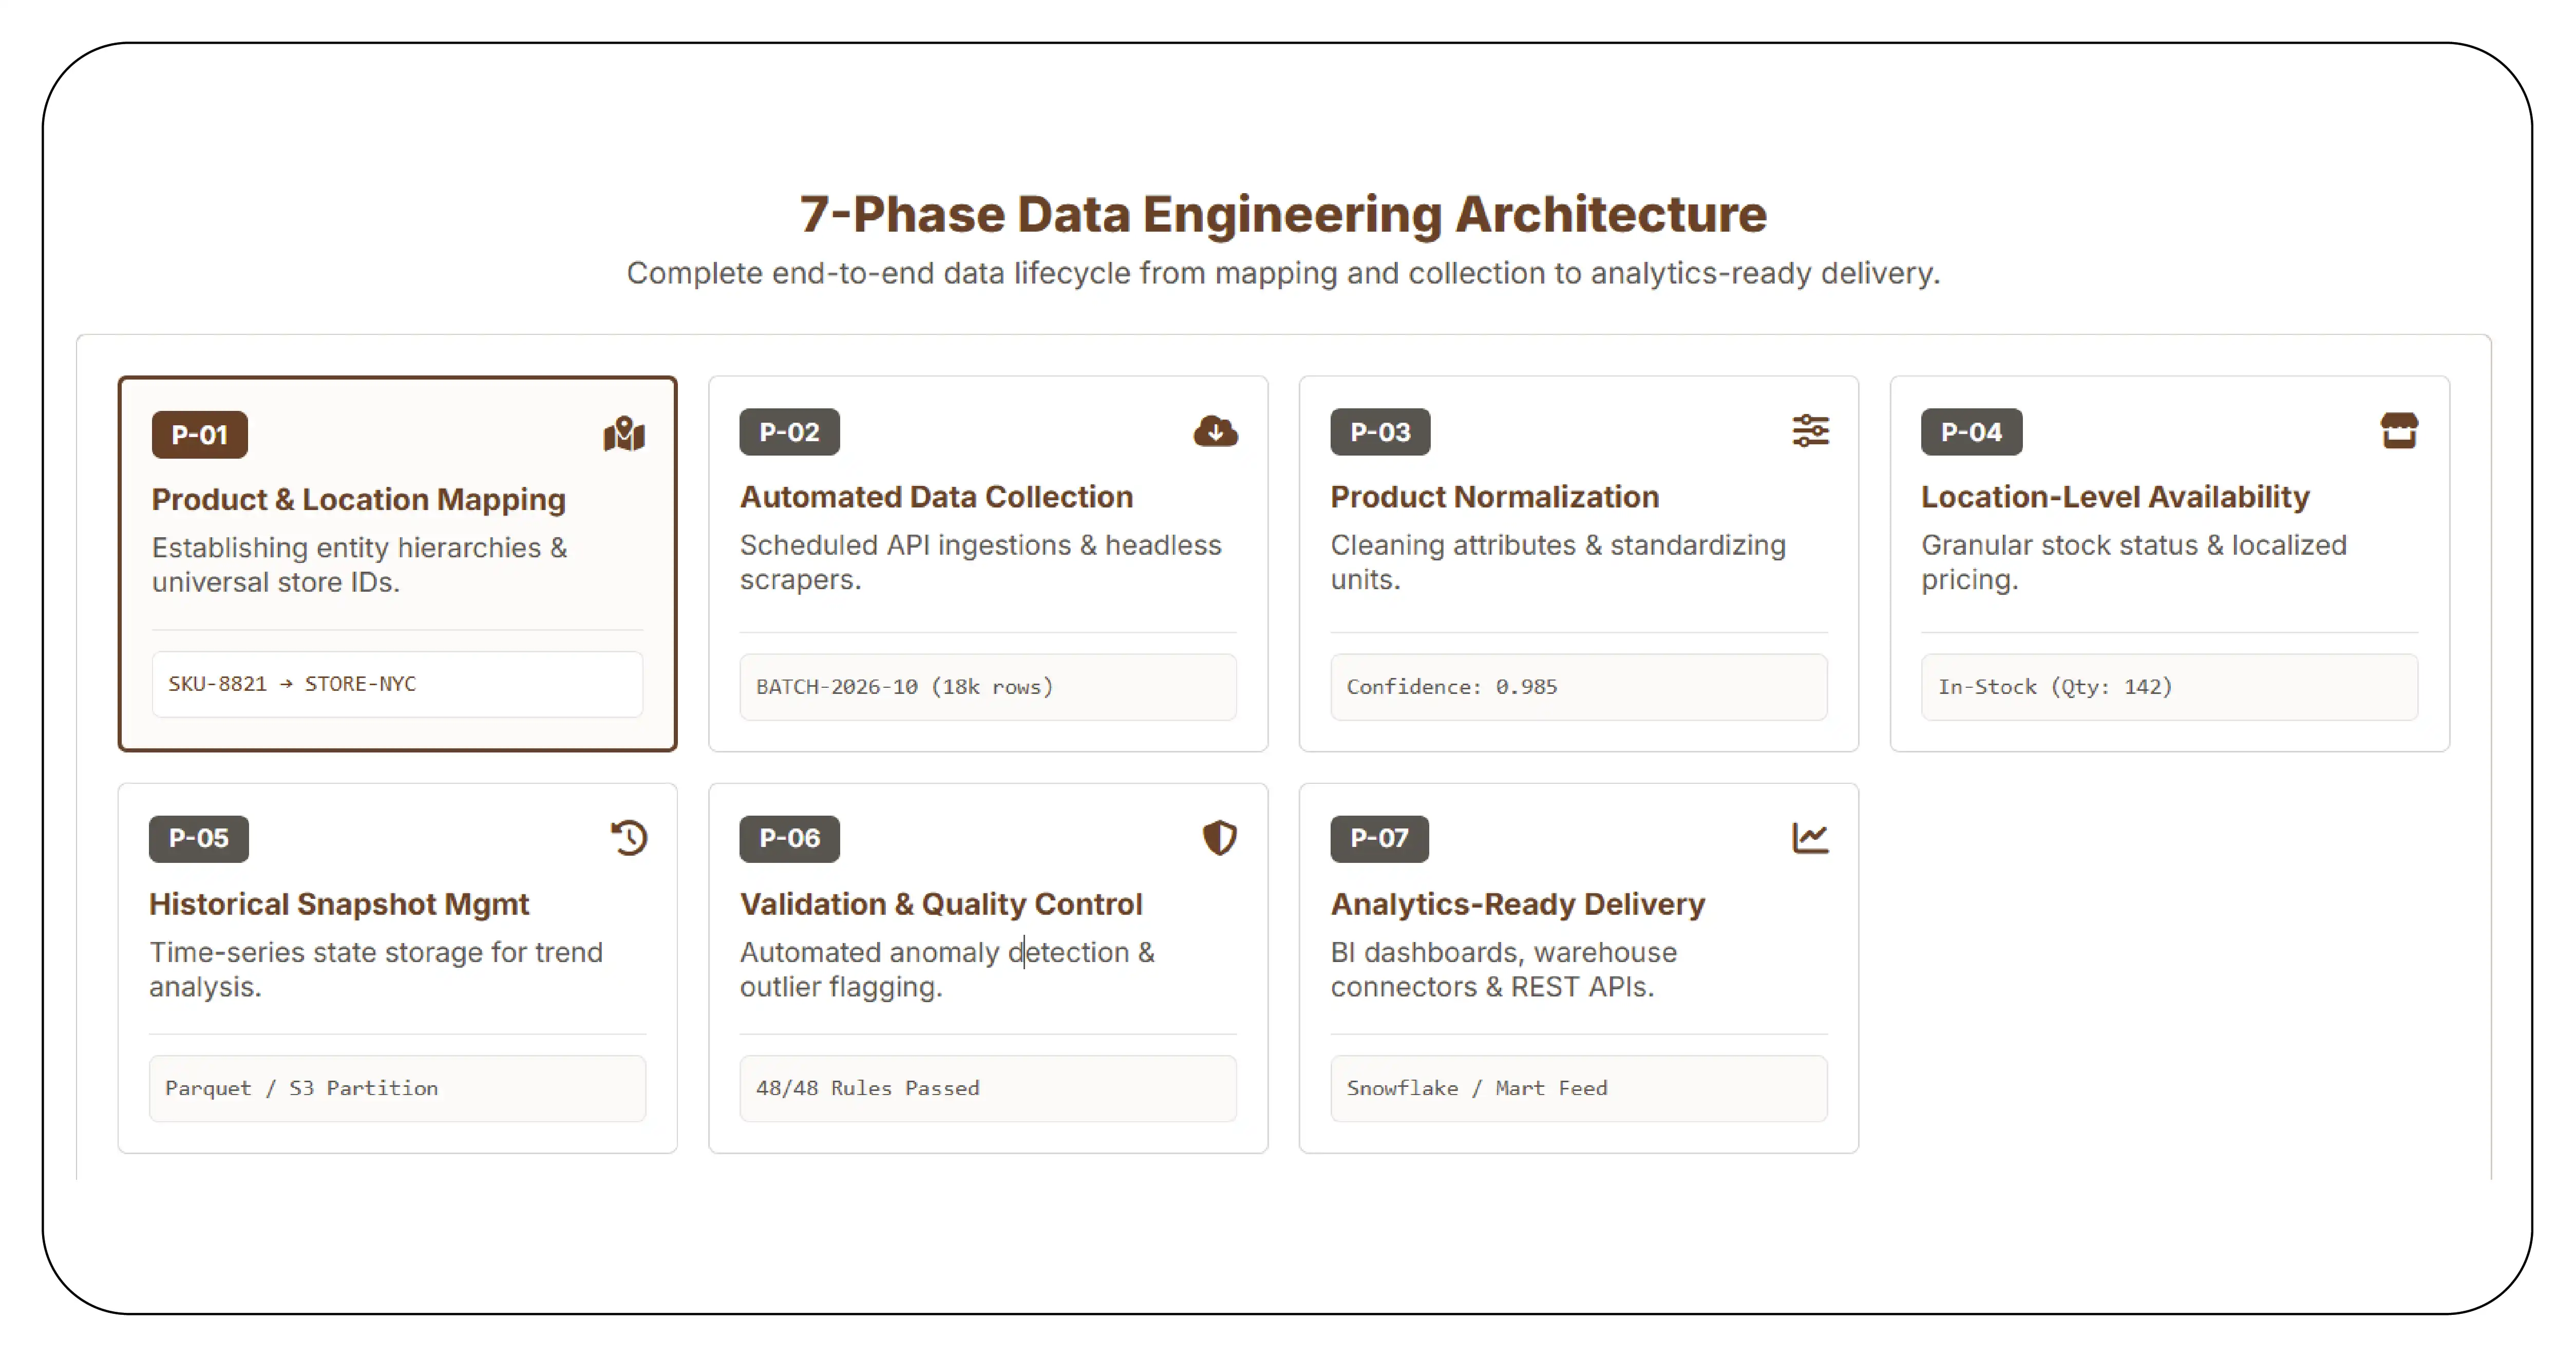
Product Data Scrape designed a phased monitoring workflow focused on scalability, consistency, and recurring availability intelligence.
Phase 1: Product and Location Mapping
The first stage established the monitoring universe. Target SKUs, product categories, brands, and more than 50 service locations were mapped into a structured configuration. Each monitoring record was associated with product identifiers and location parameters. This created a standardized foundation for recurring collection and ensured that the same product-location combinations could be evaluated consistently.
Phase 2: Automated Data Collection
The second phase introduced automated collection of product-level information. The system captured relevant product attributes, availability indicators, rankings, pricing fields where required, pack-size information, product URLs, and collection timestamps. The automation reduced the need for analysts to perform repetitive location-by-location checks and made recurring monitoring practical at a larger scale.
Phase 3: Product Normalization
Raw records were processed to create consistent fields. Product names, brands, categories, pack sizes, and availability labels were standardized according to predefined rules. This step was important because identical or comparable products can be presented differently across digital listings. Normalization helped ensure that records could be compared more reliably.
Phase 4: Location-Level Availability Processing
The system then organized observations by SKU and location. Each product-location combination received a timestamped availability state. This enabled the business to identify patterns such as available across most monitored locations, unavailable in selected locations, newly listed products, products disappearing from monitored locations, products returning to availability, and location-specific assortment differences. The core Blinkit product ranking and availability data was retained alongside product and location attributes so that business teams could analyze both visibility and availability rather than treating stock status as an isolated metric.
Phase 5: Historical Snapshot Management
Instead of overwriting previous observations, the workflow retained historical records. Each collection cycle created a new timestamped snapshot. This allowed teams to compare current and previous states and identify changes over time. Historical data also created a foundation for calculating availability rates, stockout duration, location-level performance, and product-level trends.
Phase 6: Validation and Quality Control
Automated validation rules checked for missing fields, duplicate records, unexpected status values, incomplete product information, and abnormal changes. Where a product disappeared from a location, the system treated the event as a change requiring validation rather than immediately assuming discontinuation or permanent stockout.
Phase 7: Analytics-Ready Delivery
The final dataset was structured for business analysis and recurring reporting. Product, SKU, location, availability, ranking, and timestamp fields could be consumed by analytics teams for dashboards and performance reporting. This end-to-end Blinkit Product Availability Tracking Across 50+ Locations framework transformed scattered location-level observations into a repeatable monitoring workflow.
Results & Key Metrics
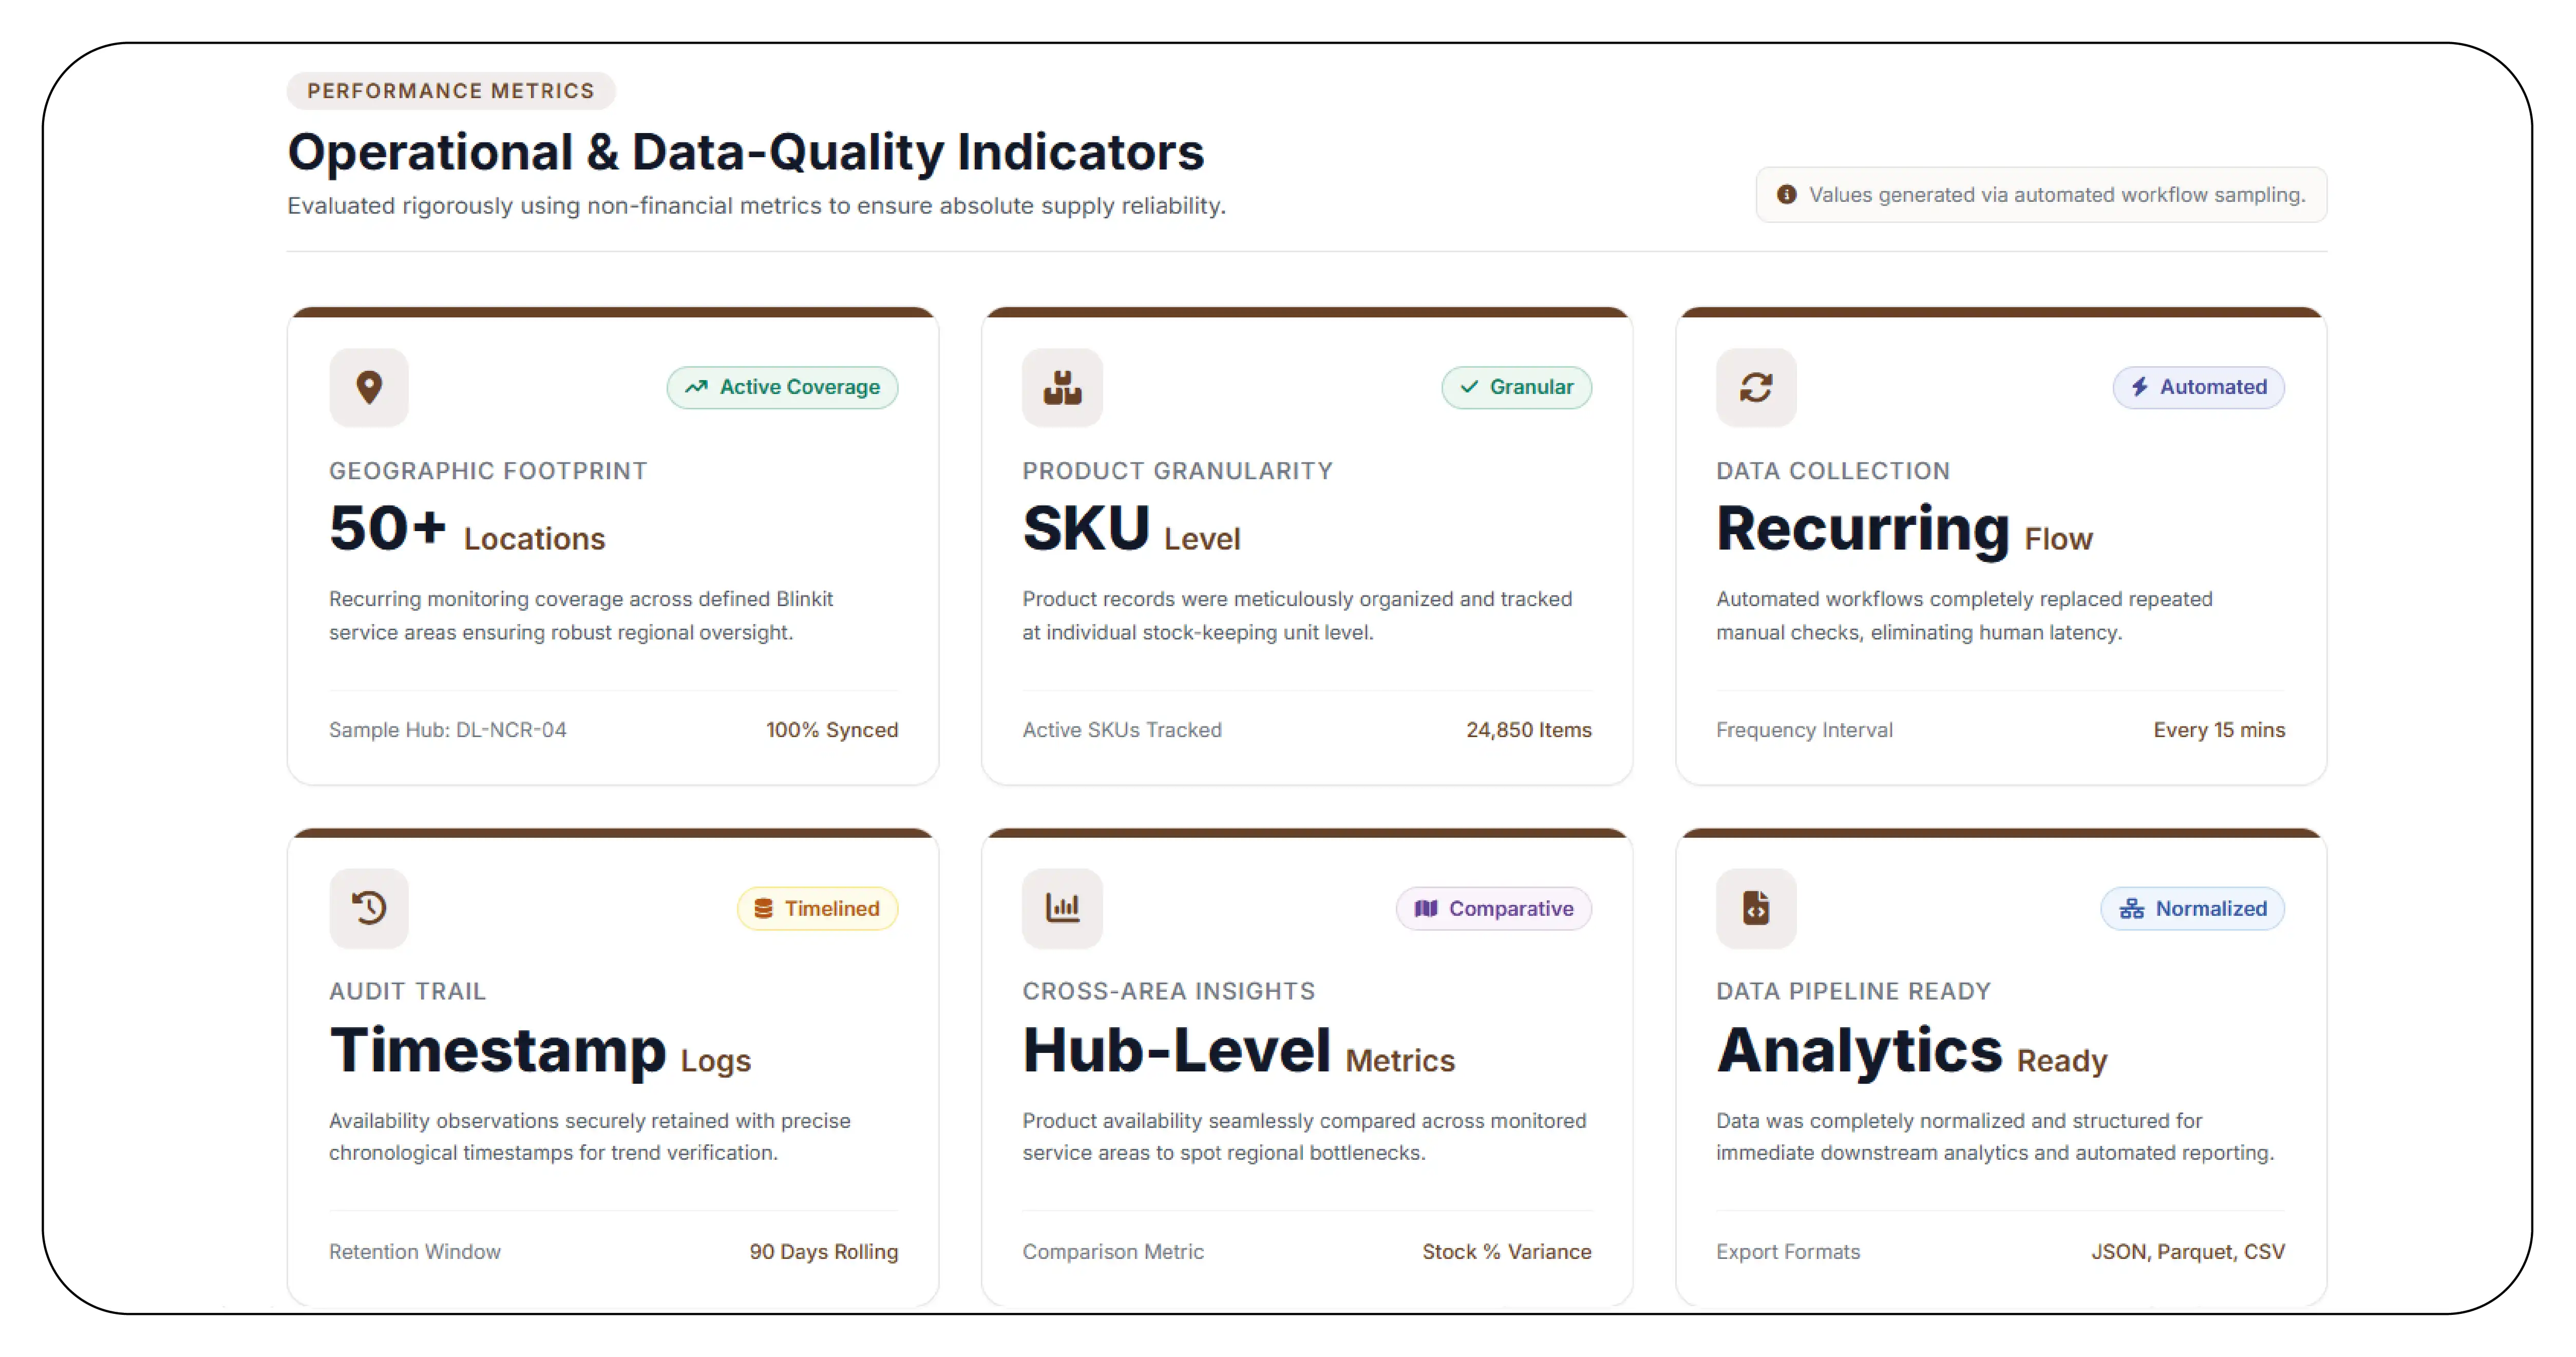
The project was evaluated using operational and data-quality indicators rather than financial savings.
50+ locations: Recurring monitoring coverage across defined Blinkit service areas.
SKU-level visibility: Product records were organized at individual SKU level.
Recurring collection: Automated workflows replaced repeated manual checks.
Historical tracking: Availability observations retained with timestamps.
Location-level analysis: Product availability could be compared across monitored service areas.
Structured output: Data was normalized for downstream analytics and reporting.
Results Narrative
The implementation gave the client a consistent framework for analyzing Blinkit product data across multiple locations. Instead of relying on isolated manual checks, teams could examine availability by SKU, location, product category, and collection period.
The historical structure also made it possible to identify recurring availability gaps and distinguish them from isolated observations. Location-level comparisons helped teams understand where product visibility differed and where additional operational investigation might be required.
The solution also created a foundation for broader quick-commerce intelligence. As location coverage and monitored SKUs expand, the same architecture can accommodate additional products, locations, categories, and analytical dimensions without rebuilding the workflow from scratch.
What Made Product Data Scrape Different
The differentiator was the combination of automation, SKU-level organization, location-specific monitoring, historical snapshots, and validation.
Rather than treating product availability as a one-time extraction task, Product Data Scrape structured the workflow around recurring observations. The system could associate every record with a product, location, status, and timestamp, creating a historical evidence layer for analysis.
The framework also supported Blinkit availability data for FMCG analytics, allowing product and availability observations to be transformed into structured business intelligence.
Smart validation reduced the risk of interpreting missing records as genuine stockouts. Location-level processing made it possible to identify geographic patterns that national-level summaries could conceal.
The architecture was also designed for expansion, enabling additional locations, SKUs, categories, and monitoring frequencies to be incorporated as business requirements evolved.
Client's Testimonial
"The project gave our team a much clearer view of product availability across individual quick-commerce locations. Instead of relying on periodic manual checks, we could work with structured, recurring data and identify location-level changes more efficiently. The historical availability records were particularly useful for understanding recurring gaps and supporting our merchandising discussions."
— Head of E-Commerce & Digital Commerce, Leading FMCG Brand
Illustrative testimonial; replace with the approved client quote and designation before publication.
The engagement demonstrated how Quick commerce & FMCG data can support practical visibility into product presence, assortment, rankings, and location-level availability. The structured approach also provided a foundation for expanding monitoring as the brand's digital distribution footprint grows.
Conclusion
The client needed a scalable way to understand how product availability changed across Blinkit locations. The resulting solution combined automated collection, SKU-level organization, location mapping, validation, and historical snapshots to create a repeatable availability-monitoring framework.
For consumer brands, Q-Commerce data scraping can provide structured visibility into fast-changing digital retail environments where product availability varies by location and time. The same framework can be expanded to additional SKUs, cities, categories, and quick-commerce platforms.
The project demonstrates that effective availability intelligence requires more than collecting a current stock status. It requires consistent monitoring, historical context, and actionable location-level data.
Partner with Product Data Scrape to build a scalable quick-commerce data solution for product availability, assortment, rankings, and multi-location monitoring!
FAQs
1. Why monitor Blinkit availability by location?
Availability can differ between service areas. Location-level monitoring helps brands identify geographic stock gaps, compare product presence, and understand where customers may encounter unavailable products.
2. What fields can a Blinkit monitoring dataset contain?
Depending on the use case, records can include SKU, product name, brand, category, pack size, availability, ranking, location, product URL, timestamp, and other accessible attributes.
3. How does automated monitoring improve availability analysis?
Automation enables recurring observations across many locations, reduces repetitive manual checks, maintains consistent collection schedules, and creates historical records for identifying availability changes.
4. Can the monitoring framework scale beyond 50 locations?
Yes. A structured architecture can expand to additional locations, SKUs, categories, monitoring frequencies, and other quick-commerce sources based on the business's requirements.
5. How can Product Data Scrape support FMCG brands?
Product Data Scrape can develop recurring product-data workflows that collect, normalize, validate, and organize digital shelf information for availability, assortment, ranking, and competitive analysis.


 Singapore
 EMAIL
 PHONE


.webp)
.webp "thumb")




.webp)